I wanted one local request to produce useful text at 100 tokens per second after a full 260,864-token input. The Mac has 512 GiB of memory and an M3 Ultra with 80 GPU cores. The experiments ran from 28 September to 6 October 2026, Asia/Singapore. The data download contains 189 measurement records from this session.
Qwen3.8-Flash-Next reached 93.25 decode tokens/s with TensorFold 0.6.5, 4-bit weights, and MTP. It passed the fixed checks on one request. The first output arrived after 735.46 seconds, or about twelve minutes. The pause after prefill accounted for 489.35 seconds of that wait.
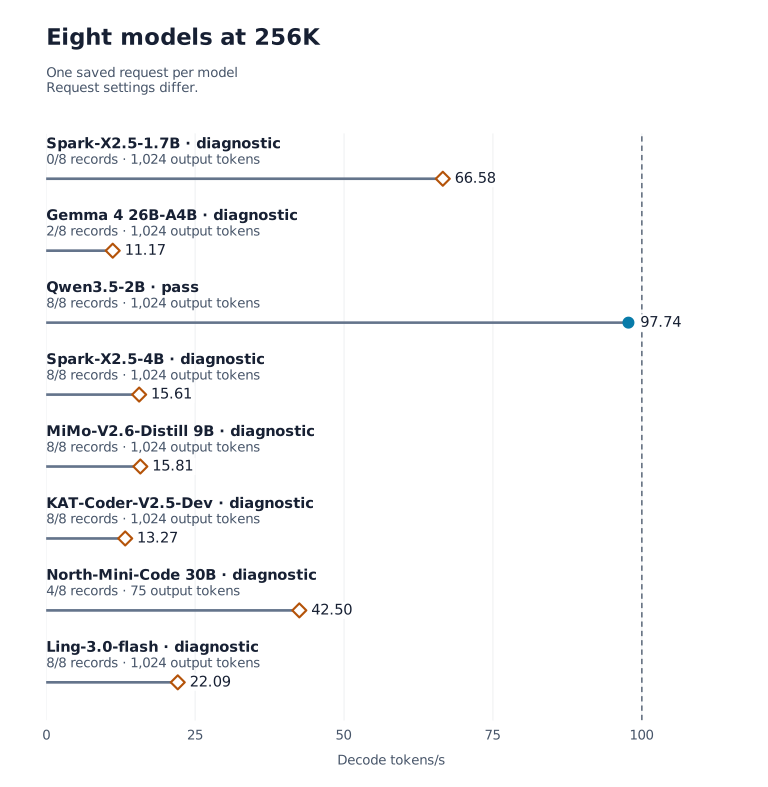
That is my best Qwen3.8 result at this depth. Qwen3.5-2B also passed the automatic checks at 97.74 tokens/s. Its other repeats and manual output review prevent a broad quality recommendation. Neither model established reliable 100 tokens/s at full context.
The pause changes the result
Prefill processes the input. Decode produces the answer tokens. A decode rate excludes the time for prefill. A fast answer can therefore follow a long initial wait. The TensorFold tests show why both times matter.


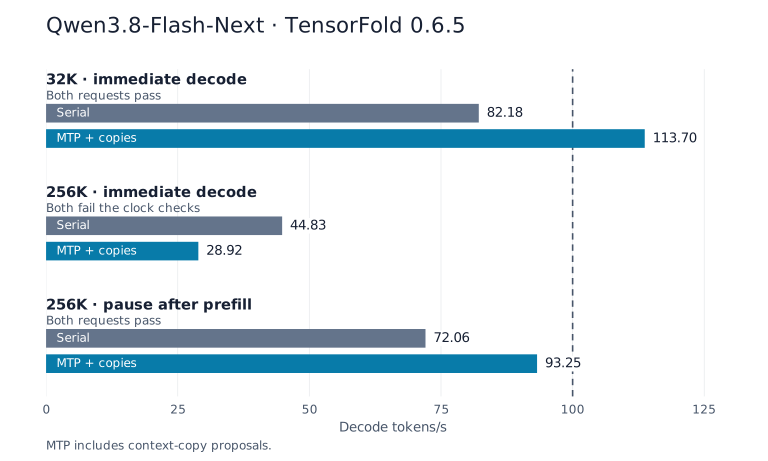


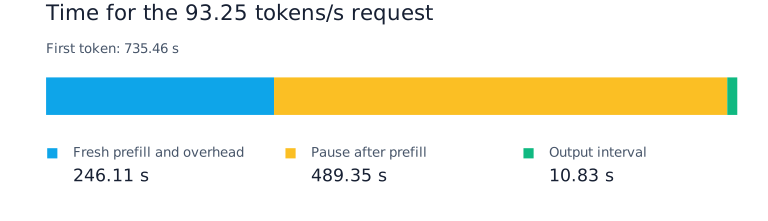
The full context stayed in the same server process during the pause. The server already computed one output token before the pause. The rate calculation excludes the first 32 output tokens. All 1,024 output tokens matched the serial control in this pair.
The tests with a pause also added a GPU check before model calibration. They therefore changed more than the pause after prefill. The comparison does not isolate the pause as the only cause of the speed difference. One pair also cannot establish repeatable service performance.
| Test | Serial t/s | MTP t/s | Serial / MTP first token, s | Both pass? |
|---|---|---|---|---|
| 2K · default | 84.78 | 111.89 | 2.50 / 2.53 | Yes |
| 32K · default | 82.18 | 113.70 | 27.78 / 27.83 | Yes |
| 256K · immediate decode | 44.83 | 28.92 | 259.29 / 410.50 | No |
| 256K · pause after prefill | 72.06 | 93.25 | 732.93 / 735.46 | Yes |
| 32K · matrix kernel | 78.05 | 101.24 | 27.82 / 27.77 | Yes |
The alternative matrix kernel was slower in both short-context controls. I did not extend that kernel test to full context. All five TensorFold MTP pairs matched their serial token sequences. MTP here also includes context-copy proposals, so the result does not isolate the native draft head.
The MTPLX variants had different limits
I tested Bare Speed and Optimized Speed packages for Qwen3.8-27B and Qwen3.8-Flash-Next. MTPLX 2.12.2 supplied the accelerated path. Every completed MTP pair differed from its serial output tokens. The measured rates remain useful diagnostic results, but they fail the exact-token condition.
The first dense full-context attempt exceeded the 3,600-second prefill limit without output. The other three dense full-context variants remain untested. Flash-Next produced full-context output, but its decode clocks stayed below the qualification limit. TensorFold used a different checkpoint, so this comparison does not isolate an engine advantage.
| Variant / mode | Decode t/s | First token, s | GPU MHz | Result |
|---|---|---|---|---|
| Qwen3.8-27B Bare Speedmtplx_serial | — | — | — | IncompletePrefill exceeded 3600 seconds |
| Qwen3.8-Flash-Next Bare Speedmtplx_mtp | — | — | — | IncompleteSystem load exceeded16 twice |
| Qwen3.8-Flash-Next Bare Speedmtplx_serial | — | — | — | IncompleteSystem load exceeded the qualification limit; the TensorFold control takes priority |
| Qwen3.8-Flash-Next Bare Speedmtplx_serial | — | — | — | IncompleteRuntimeError('[METAL] Command buffer execution failed: Caused GPU Timeout Error (00000002:kIOGPUCommandBufferCallbackErrorTimeout).') |
| Qwen3.8-Flash-Next Bare Speedmtplx_serial | 23.35 | 2,322.45 | 885.0 | Diagnostic |
| Qwen3.8-Flash-Next Optimized Speedmtplx_mtp | 33.60 | 2,524.62 | 539.0 | Diagnostic |
| Qwen3.8-Flash-Next Optimized Speedmtplx_serial | 21.58 | 2,382.92 | 853.5 | Diagnostic |
The complete table also contains every short-context variant and each failed condition.
GLM-5.3-Flash: three variants across TensorFold versions
The optimized checkpoints use mixed precision. oQ4 uses a 4-bit default with module overrides at 5, 6, and 8 bits. oQ2 uses a 2-bit default with module overrides at 4 and 8 bits. The quantization group size is 64 in all three configurations.
TensorFold 0.3.6.3
I tested standard 4-bit, oQ4, and oQ2 checkpoints. Each checkpoint received a serial/MTP pair at each of the three input depths. All requests completed, and all nine pairs produced identical tokens. None of the full-context requests passed the normal GPU-clock conditions.
These GLM tests used TensorFold 0.3.6.3 with a small, isolated compatibility patch. The patch changed loader compatibility, not kernel arithmetic or weights. One server stayed resident for each checkpoint, with prompt-cache retention disabled.
| Checkpoint | Serial t/s | MTP t/s | Serial / MTP GPU MHz | Output limit |
|---|---|---|---|---|
| GLM-5.3-Flash 4-bit | 16.15 | 17.83 | 338.0 / 389.0 | Eight correct answer-first records; guide facts remain unverified. |
| GLM-5.3-Flash oQ4 | 13.26 | 16.23 | 338.0 / 353.5 | Eight correct answer-first records; guide facts remain unverified. |
| GLM-5.3-Flash oQ2 | 12.19 | 17.26 | 339.0 / 425.0 | Correct records appear in deliberative text; answer-first format fails. |
The 2K oQ2 answer repeated a list of function names after the correct records. The other two checkpoints produced partial Python code. These tests did not establish its functional correctness.
The standard checkpoint reached 98.91 tokens/s in its shorter accelerated test. That answer retrieved only 1/8 records and copied an archive passage. The other two checkpoints failed the same task. A high token rate can measure an incorrect answer efficiently. All GLM results retain that distinction.
TensorFold 0.6.5
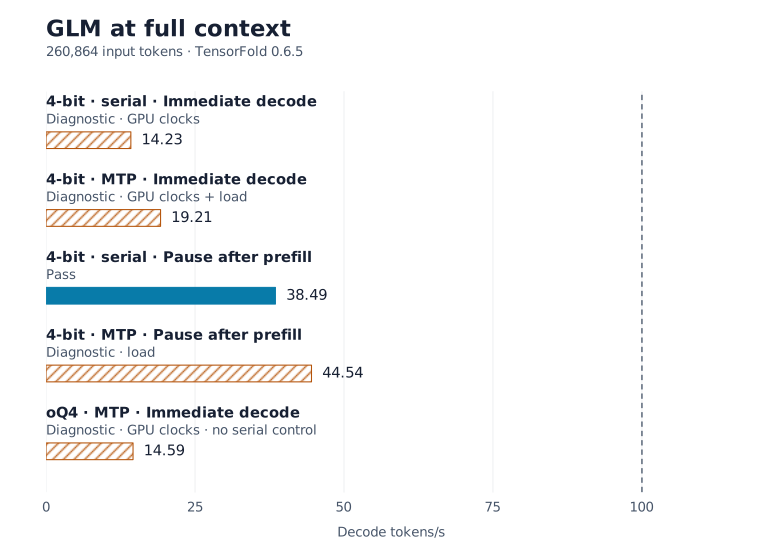
The best qualified full-context GLM request reached 38.49 tokens/s with GLM-5.3-Flash 4-bit. It produced 1,024 output tokens after 1,580.54 seconds to the first token. Its pause after prefill lasted 255.88 seconds. The table separates qualified results from rates that failed a machine or output condition.


| Checkpoint / input | Mode | Decode t/s | First token, s | Pause, s | GPU MHz | Result |
|---|---|---|---|---|---|---|
| GLM-5.3-Flash 4-bit260,864 tokens | MTP + copies | 19.21 | 1,228.41 | 0.00 | 397.0 | Diagnostic |
| GLM-5.3-Flash 4-bit260,864 tokens | MTP + copiesPause after prefill | 44.54 | 1,355.33 | 251.02 | 1,380.0 | Diagnostic |
| GLM-5.3-Flash 4-bit260,864 tokens | Serial | 14.23 | 1,328.49 | 0.00 | 338.0 | Diagnostic |
| GLM-5.3-Flash 4-bit260,864 tokens | SerialPause after prefill | 38.49 | 1,580.54 | 255.88 | 1,380.0 | Pass |
| GLM-5.3-Flash oQ4260,864 tokens | MTP + copiesDirect model load | 14.59 | 1,225.57 | 0.00 | 343.0 | Diagnostic |
The complete records also contain all short-context tests and incomplete attempts.
The new tests used the same standard 4-bit, oQ4, and oQ2 checkpoints. They used a greedy sampler, the current archive task, and a fresh server for each request. The saved input-token hashes differ between versions at all three depths. These changes prevent a version-only speed comparison. All 34 attempts ended: 20 requests completed, and 14 attempts failed. No qualified full-context GLM request reached 100 tokens/s.
Both full-context oQ2 baseline attempts stopped at the system-load guard without output. They have no decode rate. The complete index retains these attempts and their saved failure evidence.
Model setup and failed attempts
The first startup exceeded its 24-minute allowance before a measured request began. The recovery uses the earlier GLM one-hour startup allowance and a sequential host read before the GPU load. It creates no local weight copy. These setup times remain outside the measured request and its first-token time. The new records include that failed attempt with no decode rate.
The first oQ4 model load failed with a Metal GPU timeout before any measured request. The error occurred when the loader evaluated weight arrays. The saved trace does not establish its cause. The next attempt retained the same runtime and measurement settings. That retry loaded the checkpoint and completed the 2K serial test. Both attempts remain in the record.
The separate host read took 34.7 minutes before that successful model load required another 40.5 minutes. The revised queue loads the existing NAS weights directly. The repeated oQ4 serial control produced identical input and output tokens. I stopped the next MTP setup before a server start for this setup change. That partial setup has no decode rate.
A later full-context oQ4 serial attempt stopped after two load samples exceeded 16. Its last prefill record contained 131,072 tokens. It produced no output and has no decode rate. The process snapshot followed the spike and did not establish its cause. Its paired MTP request completed later, but its serial exactness check remains unavailable.
The first oQ4 serial pause setup also failed with a Metal GPU timeout before the measured request. Its stack identified KDA weight materialization; the earlier timeout identified MLA weight materialization. The next baseline serial retry also failed at MLA weight materialization. The traces do not establish the cause. The record retains all three failures, and the oQ2 queue uses the unchanged runtime.
The first oQ2 startup also failed with a Metal GPU timeout before its measured request. A separate loader variant now completes each stored-array read before GPU layout operations. It restores its temporary hooks before the server accepts a request. The installed package files and numerical operations remain unchanged. Both reference controls reproduced the original input IDs and all 1,024 serial tokens at 2K and 32K. The tables identify this variant as “Eager array load”.
The first eager-array full-context serial request stopped after a terminal interruption during an assistant service restart. It completed 212,992 prefill tokens but produced no output. The driver restored the fans and production service. The recovery queue uses a persistent terminal and the same measurement settings. The serial retry also stopped at 163,840 prefill tokens after two load samples exceeded 16.
The eager-array MTP request also stopped at 163,840 prefill tokens after a load spike, with no output. The saved process snapshots do not establish the cause of either spike.
The first eager-array oQ2 full-context serial request also stopped at the system-load guard. It reached 114,688 prefill tokens and produced no output. Its saved load samples reached 17.81 and 19.90. The process snapshots do not establish the cause.
The full-context oQ2 MTP request also stopped at 114,688 prefill tokens, without output. Its guard samples reached 17.63 and 20.07. Both incomplete requests remain in the index with no decode rate.
The eager-array oQ4 serial pause setup exceeded its one-hour allowance before a measured request. The last saved loader count was 2,600 array reads. The server log contains no printed Metal error, and the cause remains unknown. This attempt also has no decode rate.
The final oQ4 MTP pause attempt stopped after load samples of 19.49 and 20.73. It reached 163,840 prefill tokens, with no output or decode rate. The request never reached its planned pause after prefill. The two authorized disk searches ended before these guard samples. The saved observations do not establish the cause of the load spike.
During the final MTP pause attempt, I authorized termination of two full-disk searches. Both searches ended after the last prefill record reached 163,840 tokens. Their role in the earlier load spikes remains unproved. This intervention prevents a comparison under identical background conditions.
The native GLM cache uses BF16 latent and indexer arrays, with FP32 KDA state. The server starts with no retained prompt cache for each request. A separate pause test retains the complete context after prefill. Its first-token time includes the pause. The appendix lists each failed condition and the manual output review.
The eight-model test: small weights did not settle the question
The release audit inspected recent catalogs from 30 publishers and 56 individual model or artifact repositories. This was a broad search, not a complete list of every release. The test queue included the models below. Ling joined the measured queue; Qwen3-Coder-Next remained a research candidate.


| Model | Decode t/s | Output tokens | Recall | Result |
|---|---|---|---|---|
| Spark-X2.5-1.7B protected 8-bitserialmlx-lm 0.32.1.dev4+g53b9af378 | 66.58 | 1,024 | 0/8 | Diagnostic |
| Gemma 4 26B-A4B QAT 4-bitserialmlx-lm 0.32.1.dev4+g53b9af378 | 11.17 | 1,024 | 2/8 | Diagnostic |
| Qwen3.5-2B 4-bitserial_kv4_after_prefillmlx-lm 0.32.1.dev4+g53b9af378 | 97.74 | 1,024 | 8/8 | Pass |
| Spark-X2.5-4B 8-bitserialmlx-lm 0.32.1.dev4+g53b9af378 | 15.61 | 1,024 | 8/8 | Diagnostic |
| MiMo-V2.6-Distill-Qwen-9B mixed 4/6-bitserial_prefill_pause2000msmlx-lm 0.32.1.dev4+g53b9af378 | 15.81 | 1,024 | 8/8 | Diagnostic |
| KAT-Coder-V2.5-Dev OptiQ 4-bitserial_prefill_pause2000msmlx-lm 0.32.1.dev4+g53b9af378 | 13.27 | 1,024 | 8/8 | Diagnostic |
| North-Mini-Code-1.0 4-bitserial_prefill_pause2000msmlx-lm + mlx-vlm model 0.32.1.dev4+g53b9af378 | 42.50 | 75 | 4/8 | Diagnostic |
| Ling-3.0-flash 4-bitserial_prefill_pause2000msmlx-lm + local Ling adapter 0.32.1.dev4+g53b9af378 | 22.09 | 1,024 | 8/8 | Diagnostic |
These rows do not form a comparison under identical conditions. Some retries added pauses between prefill blocks. North produced a short answer, which does not establish sustained speed. Several models returned all records but failed the clock or load checks. The complete records include those conditions and the earlier failures.
The closest small model still had answer defects
Qwen3.5-2B supplied a useful cache experiment. Each variant used the same target weights and converted the KV cache after prefill where applicable. Smaller cache values increased decode speed. They did not establish reliable output quality.


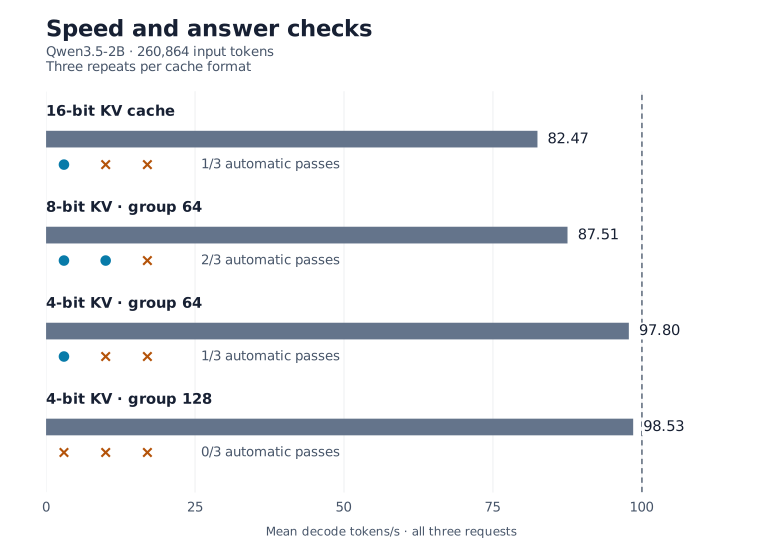
| KV cache | Repeats | Mean tokens/s | Automatic passes |
|---|---|---|---|
| 16-bit | 3 | 82.47 | 1/3 |
| 8-bit, group 64 | 3 | 87.51 | 2/3 |
| 4-bit, group 64 | 3 | 97.80 | 1/3 |
| 4-bit, group 128 | 3 | 98.53 | 0/3 |
These means include failed answers. The fastest mean did not produce any automatic pass. Manual review also found unsupported factual claims in the guides. Correct retrieval of the fixture records does not make the rest of an answer correct.
MiMo: the MTP label needed a source check
The inspected official MiMo-V2.6-Distill-Qwen-9B configuration declared an MTP layer. Its tensor index contained no MTP weights. Community packages supplied different heads, so their names did not describe one equivalent accelerator.
- The Youssofal MTPLX package used a borrowed Qwen3.5-9B head.
- The VitreousCut GGUF package used a separately trained draft head.
- The ycui7 NVFP4 package contained MTP tensors, but their source claim remained unresolved.
The local MTPLX short test differed from its serial tokens. It also used context-copy proposals. That result did not justify a full-context exactness claim, so the longer accelerator tests remained untested. The ordinary mixed-precision model appears in the eight-model table above.
I also inspected the larger Flash and Pro artifacts without a large weight download. The official Flash-MOPD safetensors totaled 177.741 GB. The inspected Pro artifacts totaled 573.457 GB, above this machine's physical memory before its other requirements. Weight size alone does not establish runtime support or decode speed. The source index identifies the pinned MiMo investigation.
The earlier experiments explain the controls
mlx.fast: a fast contest engine can fail on another GPU
The Bonsai challenge used an M5 and a short prompt. I checked the selected engines on this M3 Ultra. All 11 promoted submissions matched the serial reference in the correctness probe. Their submitted DFlash configuration produced invalid output almost immediately on M3.
The investigation isolated a Metal tensor-operation path with M5-specific fragment indices. The kernel selected that path from the language version instead of the GPU type. A smaller verification width avoided that path. This repaired the immediate corruption, but it did not establish a speed advantage.
| Engine / mode | Actual input | Decode t/s | Final-answer recall |
|---|---|---|---|
| ctl_dflash10mlx.fast Swift/Metal · Reference 88cf569e88 | 31,958 | 13.38 | 5/8 |
| ctl_serial_1mlx.fast Swift/Metal · Reference 88cf569e88 | 31,958 | 27.36 | 8/8 |
| winglock_dfsafe10mlx.fast Swift/Metal · Winglock 831fae740d | 31,958 | 26.03 | 7/8 |
| winglock_serialmlx.fast Swift/Metal · Winglock 831fae740d | 31,958 | 34.07 | 8/8 |
The performance matrix remained incomplete when the session moved to other candidates. These measurements use the near-32K fixture. They do not establish a full-context result. Source records.
E9 and the first TensorFold tests
Flash-Next E9 used ENGINE with native MTP. A separate replay reused almost the complete prompt cache after a pause. Its faster answer did not measure fresh prefill. The early TensorFold Nemotron and Flash-Next tests also encountered reduced clocks or fan-control failures.
| Model / mode | Decode t/s | Cached input | GPU MHz | Recall |
|---|---|---|---|---|
| Nemotron Lightning 4-bitMTP + context copiesTensorFold 0.3.6.3 | 8.97 | 0 | 338.0 | 7/8 |
| Nemotron Lightning 4-bitSerialTensorFold 0.3.6.3 | 71.07 | 0 | 942.0 | 7/8 |
| Qwen3.8-Flash-Next 4-bit pilotMTP + context copiesTensorFold 0.3.6.3 | 16.03 | 0 | 338.0 | 8/8 |
| Qwen3.8-Flash-Next 4-bit pilotSerialTensorFold 0.3.6.3 | 16.81 | 0 | 338.0 | 8/8 |
| Qwen3.8-Flash-Next E9 8-bitENGINE native MTPENGINE f5078d8206 | 24.57 | 0 | 338.0 | 8/8 |
| Qwen3.8-Flash-Next E9 8-bitENGINE native MTPENGINE f5078d8206 | 24.25 | 0 | 338.0 | 8/8 |
| Qwen3.8-Flash-Next E9 8-bitENGINE native MTPENGINE f5078d8206 | 59.11 | 260,894 | 923.0 | 8/8 |
None of these full-context rows passed the complete performance conditions. Both Nemotron answers contained the same incorrect city name, despite the correct code string. The early Flash-Next pilot used a temperature-1 sampler and a different TensorFold version. Its difference from the final test cannot measure a version-only speed increase. E9, Nemotron, and Flash-Next retain separate records.
The exact Ollama package completed only the shorter tests
I tested qwen3.8:27b-mlx with both shipped Metal backends.
Each shorter configuration completed two repeats.
Four full-context attempts stopped during prefill after large load increases.
Those interruptions have no full-context decode rate.
| Backend | Input tokens | Repeats | Median tokens/s |
|---|---|---|---|
| mlx_metal_v3 | 2,048 | 2 | 83.12 |
| mlx_metal_v3 | 32,768 | 2 | 48.30 |
| mlx_metal_v4 | 2,048 | 2 | 85.55 |
| mlx_metal_v4 | 32,768 | 2 | 47.17 |
The attempt records preserve the incomplete requests beside the completed results.
Engines and exact versions
The engine runs the model and produces output tokens. These runs used the versions below, with the recorded model packages and request settings. Every measurement in the appendix links to its engine entry. The JSON download also contains each runtime ID, package version, source revision, and local-change note.
The MiMo accelerator test used MTPLX 2.12.0 with MLX 0.32.3. The later Qwen MTPLX tests used MTPLX 2.12.2 with MLX 0.32.2. The eight-model baseline used a development revision of mlx-lm. North and Ling required the adapters identified below. The Gemma assistant tests used mlx-vlm, while the earlier Gemma baseline used mlx-lm.
| Runs covered | Engine / version | Core packages | Local changes and source |
|---|---|---|---|
| Final Qwen3.8-Flash-Next TensorFold tests and all new GLM tests.44 records | TensorFold0.6.5 609ca419abecebdc5a059498a613680bd3aa847f Engine source | mlx 0.32.2 mlx-lm 0.31.3 | The matrix arms set TF_FLASH_DENSE=matrix.The GLM eager_load arms add a local array-read boundary before GPU layout operations.The eager loader restores its hooks before each request. Saved version evidenceqwen38_variants_bench/tensorfold-source.jsonqwen38_variants_bench/tensorfold-integrity.jsonglm53_tensorfold065_bench/runtime-integrity-start.jsonglm53_tensorfold065_bench/eager_weights.py |
| Qwen3.8-27B and Flash-Next Bare Speed and Optimized Speed tests.23 records | MTPLX2.12.2 | mlx 0.32.2 mlx-lm 0.31.3 | Serial and MTP arms use the same target package.MTP can combine the native draft head with context-copy proposals. Saved version evidenceqwen38_variants_bench/runtime-integrity.json |
| Early Nemotron and Qwen3.8-Flash-Next tests.21 records | TensorFold0.3.6.3 191188075bca56a7c71074a79375eb4c1cb22e1c Engine source | mlx 0.32.2 mlx-lm 0.31.3 | These tests use the temperature-1 protocol.The accelerated arms include native MTP and context copies. Saved version evidencedocs/20260929_tensorfold_nemotron_256k.mdtensorfold_bench/requirements.lock.txtflashnext_bench/requirements.lock.txt |
| Earlier GLM standard 4-bit, oQ4, and oQ2 tests.18 records | TensorFold0.3.6.3 + local compatibility patch 191188075bca56a7c71074a79375eb4c1cb22e1c Engine source | mlx 0.32.2 mlx-lm 0.31.3 | The patch adjusts affine-width acceptance and tokenizer setup.It changes no numerical kernel or model weight. Saved version evidenceglm53_bench/runtime-provenance.jsonglm53_bench/runtime.patchdocs/20260930_glm53_flash_variants.md Patch SHA256: 13667562e648fae56db51a20b2633a7653cb5655bdc9709ce84c65a3079d3d66. |
| Spark, Qwen3.5-2B, Gemma baseline, MiMo baseline, KAT, and the first failed Ling load.44 records | mlx-lm0.32.1.dev4+g53b9af378 53b9af378278d6dd5dacac447edeb0f523b16253 Engine source | mlx 0.32.2 | This group includes the Qwen KV cache variants and prefill-pause serial requests.The first Ling load failed before the local adapter was added. Saved version evidenceeight_models_bench/runtime-integrity.jsoneight_models_bench/worker.py |
| All North-Mini-Code requests.7 records | mlx-lm + mlx-vlm model0.32.1.dev4+g53b9af378 53b9af378278d6dd5dacac447edeb0f523b16253 Engine source | mlx 0.32.2 mlx-vlm 0.7.4 66e68ce36816cb5134acba3b0d72c6271f35ba24 | mlx-lm supplies the generation loop.The mlx-vlm Cohere model uses a local logits-only return adapter. Saved version evidenceeight_models_bench/runtime-integrity.jsoneight_models_bench/worker.py |
| Ling requests after the initial weight-validation failure.4 records | mlx-lm + local Ling adapter0.32.1.dev4+g53b9af378 53b9af378278d6dd5dacac447edeb0f523b16253 Engine source | mlx 0.32.2 | The adapter comes from the TensorFold model package, with local decay, normalization, and beta-precision corrections.The TensorFold inference server does not execute these requests. Saved version evidenceeight_models_bench/runtime-integrity.jsoneight_models_bench/ling_adapter.pyeight_models_bench/ling/ADAPTER.md Adapter helper SHA256: 2cab71f8ad08c24865c518389db9e395f35d41f83971737d4dad5ff6f94a86d6. |
| Gemma assistant tests with gemma-vlm_serial and gemma-vlm_mtp modes.6 records | mlx-vlm0.7.4 66e68ce36816cb5134acba3b0d72c6271f35ba24 Engine source | mlx 0.32.2 mlx-lm 0.32.1.dev4+g53b9af378 53b9af378278d6dd5dacac447edeb0f523b16253 | These short accelerator tests use the direct mlx-vlm bridge.The earlier Gemma baseline requests use mlx-lm. Saved version evidenceeight_models_bench/runtime-integrity.jsoneight_models_bench/accel_engines.py |
| MiMo 9B MTPLX serial and MTP accelerator tests.2 records | MTPLX2.12.0 | mlx 0.32.3 mlx-lm 0.31.3 | This separate environment uses the 6-bit target and the borrowed Qwen draft head.These tests differ from the mixed-precision MiMo baseline. Saved version evidenceeight_models_bench/mtplx-runtime-integrity.jsoneight_models_bench/accel_engines.py |
| qwen3.8:27b-mlx requests with the mlx_metal_v3 backend.5 records | Ollama / mlx_metal_v30.35.0 Engine source | MLX backend Bundled with Ollama 0.35.0 | Both Metal backends come from the same verified Ollama release archive. Saved version evidenceqwen38_27b_bench/runtime-version.jsonqwen38_27b_bench/runtime-verification.json Archive SHA256: 2608dbb0a0f0136a198db9d48b4f74ece55f452314a39452fca35b7cf20c2589. |
| qwen3.8:27b-mlx requests with the mlx_metal_v4 backend.7 records | Ollama / mlx_metal_v40.35.0 Engine source | MLX backend Bundled with Ollama 0.35.0 | Both Metal backends come from the same verified Ollama release archive. Saved version evidenceqwen38_27b_bench/runtime-version.jsonqwen38_27b_bench/runtime-verification.json Archive SHA256: 2608dbb0a0f0136a198db9d48b4f74ece55f452314a39452fca35b7cf20c2589. |
| All four Flash-Next E9 requests, including the cached replay.4 records | ENGINEGit revision f5078d82065f83634383f5cc4735c81f152d3ba9 Engine source | mlx-swift Vendored source df1fdc5f7821a1fabe921fdefbc42ac74dcfb6bc mlx-swift-lm Vendored source bc1c0ee67d15798343be17c9f8f61f7c0d977149 Swift 6.3.2 | Native MTP uses depth 3 and the temperature-1 protocol.The source commit identifies the engine build. Saved version evidencee9_bench/results/run_20260929_163156/environment.txttools/engine-e9/Package.swift |
| Reference serial and DFlash-10 performance arms at 31,958 input tokens.2 records | mlx.fast Swift/Metal · ReferenceGit revision 88cf569e885019ffe637192efcbda4aaf2c32f1c | Vendored Swift/Metal source at the engine revision. | The reference build combines its source revision with the trusted harness at 831fae740de35a106e85768d8b0534b4af422b13.DFlash depth 10 is the M3 compatibility configuration. Saved version evidencemlxfast_bench/results/c32k_fans/ctl_serial_1.jsonmlxfast_bench/build_trees.shdocs/28092026_mlxfast_256k_plan.md Worker SHA256: 4e5c6324b37d9b2a3bb256e39720a9959d6efdadbec67025f8eefde5ff57db7f. |
| Winglock serial and DFlash-10 performance arms at 31,958 input tokens.2 records | mlx.fast Swift/Metal · WinglockGit revision 831fae740de35a106e85768d8b0534b4af422b13 | Vendored Swift/Metal source at the engine revision. | The Winglock build uses the recorded source revision.DFlash depth 10 is the M3 compatibility configuration. Saved version evidencemlxfast_bench/results/c32k_fans/winglock_serial.jsonmlxfast_bench/build_trees.shdocs/28092026_mlxfast_256k_plan.md Worker SHA256: 1db295e0d6c8653b3adc1dc079d5db4b702d628b7235d7782a73a8bd367a4901. |
ENGINE and the mlx.fast submissions use exact Git revisions as their version identifiers. Ollama supplies both Metal backends in its 0.35.0 release archive. A backend name such as mlx_metal_v4 is separate from the Ollama release number. The earlier TensorFold GLM tests include a compatibility patch, and the later eager-load variants include a separate setup change. These details matter when another person attempts the same experiment.
The measurement system also needed repairs
The temperature command was macmon pipe -s 1 -i 500.
The defective field was temp.gpu_temp_avg.
When all GPU sensor values were invalid, macmon returned zero from an empty average.
The benchmark could mistake an unavailable sensor for a cold GPU.
I repaired the reader and added native temperature and fan telemetry to Surge. An unavailable value now remains null. The start check requires valid current sensor coverage. Surge records temperatures and fans; macmon still records GPU clocks. The sensor interface was verified on this machine, not every Mac model.
Some earlier kernel logs recorded thermal power-budget reductions with the clock declines. These records support a power-limit explanation for those attempts. They do not identify one defective component or prove that average GPU temperature explains every decline. Low clocks also persisted with the fans at maximum speed.
The final campaign rules
- Use a fresh process and an empty request cache for each request.
- Check valid GPU temperature at or below 50°C and initial load at or below 6.
- Check both fans at or above 3,400 RPM.
- Run the fresh GEMM check and require more than 20.5 TFLOPS.
- Verify all 260,864 input tokens and retain all output tokens and their times.
- Measure the output-token slope after token 32.
- Check retrieval, repetition, output length, GPU clocks, load, and telemetry.
- Compare each MTP token sequence with its serial control.
- Restore automatic fan control and the production model service.
A qualified final request requires 1,024 output tokens and 8/8 correct fixture records. The median decode clock must reach 1,300 MHz. At most 5% of decode samples can fall at or below 400 MHz. The measured load must stay at or below 8.
The normal guard stops a request after two load samples above 16 or two low-fan samples. A start check alone cannot guarantee a clean request. Background jobs and clock changes can occur after that check. Process observations did not establish the cause of every later load increase.
The final MTPLX harness fixed prefill chunks at 1,024 tokens. The package profile specified automatic widths of 2,048 tokens. These are measurements of the recorded harness configuration, not all possible engine settings. The earlier campaigns also used different samplers and client timing methods.
The downloads had a storage budget
I used the hf CLI with fixed revisions for the final model downloads.
The NAS held the model weights.
The campaign preserved 100 GiB of local free space and 200 GiB on the NAS.
File hashes and published LFS hashes supplied artifact checks.
Existing TensorFold weights avoided another large copy. Their earlier full-hash receipt remained the source for the large files. The final campaign paused downloads before measured requests. Interface traffic and download wall time do not equal an Internet speed test.
What I can claim now
The new Qwen3.8 result shows a useful decode rate after full prefill under controlled conditions. Its long initial wait remains part of the result. Qwen3.5-2B came closer to the speed target under narrow automatic checks. Its output defects remain part of that result too.
My earlier leaderboard reported Nemotron at 60.45 tokens/s over 4 repeats. That historical baseline remains separate from these new tests. None of these retrieval fixtures establishes the best general coding model. A useful next experiment would repeat the Qwen pair in alternate order, then test code and long answers for correctness.
The complete measurement index


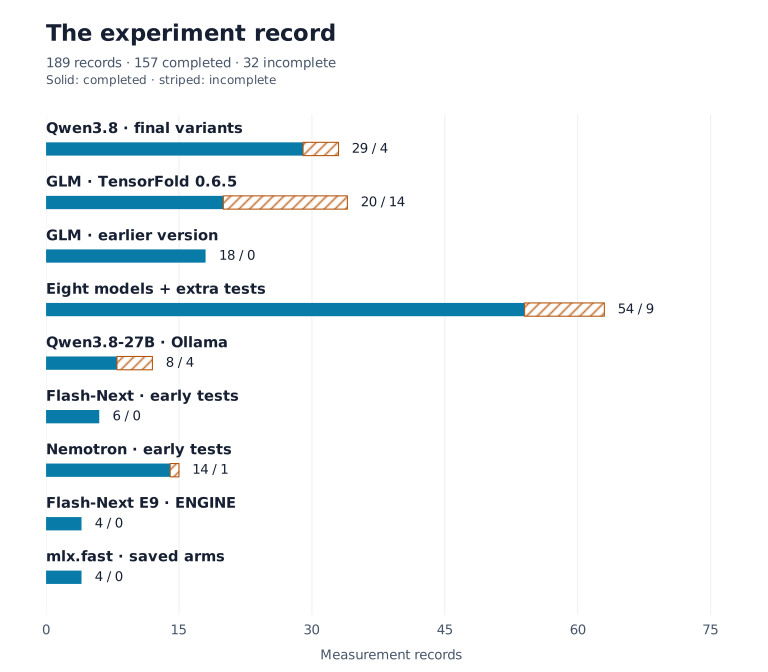
Completed and incomplete record counts
| Experiment group | Completed | Incomplete | Total |
|---|---|---|---|
| mlx.fast Bonsai engines | 4 | 0 | 4 |
| Flash-Next E9 + ENGINE | 4 | 0 | 4 |
| Early TensorFold Nemotron | 14 | 1 | 15 |
| Early TensorFold Flash-Next | 6 | 0 | 6 |
| Three GLM-5.3-Flash checkpoints | 18 | 0 | 18 |
| GLM-5.3-Flash with TensorFold 0.6.5 | 20 | 14 | 34 |
| Exact Ollama Qwen3.8-27B | 8 | 4 | 12 |
| Eight-model campaign and follow-up tests | 54 | 9 | 63 |
| Final Qwen3.8 MTPLX and TensorFold variants | 29 | 4 | 33 |
Each group below contains the exported numeric records for its experiment. “Pass” means that the request passed that campaign's checks. The checks differ between campaigns. “Diagnostic” preserves a completed measurement with a failed condition. “Incomplete” supplies no final decode rate.
Download all 189 records as JSON. The download includes timing definitions, model revisions, source hashes, and experiment IDs. Full prompts, raw traces, complete setup logs, and invalid mlx.fast attempts remain in the local research archive. The article therefore covers the experiment groups without a claim that every raw file appears in the download.
mlx.fast Bonsai engines4 records
Four validated performance arms from an incomplete matrix. The separate correctness probes covered eleven promoted engines.
| Model / mode | Input / output | Decode t/s | First token, s | GPU MHz | Recall | Result / limits |
|---|---|---|---|---|---|---|
| Ternary Bonsai 2 27Bctl_dflash10mlx.fast Swift/Metal · Reference 88cf569e88 | 31,958 / 1,024 | 13.38 | — | — | 5/8 | Separate scope Source, metric, and reviewmlxfast_bench/results/c32k_fans/ctl_dflash10.jsonFree-run output token slope |
| Ternary Bonsai 2 27Bctl_serial_1mlx.fast Swift/Metal · Reference 88cf569e88 | 31,958 / 1,024 | 27.36 | — | — | 8/8 | Separate scope Source, metric, and reviewmlxfast_bench/results/c32k_fans/ctl_serial_1.jsonFree-run output token slope |
| Ternary Bonsai 2 27Bwinglock_dfsafe10mlx.fast Swift/Metal · Winglock 831fae740d | 31,958 / 1,024 | 26.03 | — | — | 7/8 | Separate scope Source, metric, and reviewmlxfast_bench/results/c32k_fans/winglock_dfsafe10.jsonFree-run output token slope |
| Ternary Bonsai 2 27Bwinglock_serialmlx.fast Swift/Metal · Winglock 831fae740d | 31,958 / 1,024 | 34.07 | — | — | 8/8 | Separate scope Source, metric, and reviewmlxfast_bench/results/c32k_fans/winglock_serial.jsonFree-run output token slope |
Flash-Next E9 + ENGINE4 records
Four completed requests. The cached replay consumed one uncached token. These rates use the ENGINE generation counter.
| Model / mode | Input / output | Decode t/s | First token, s | GPU MHz | Recall | Result / limits |
|---|---|---|---|---|---|---|
| Qwen3.8-Flash-Next E9 8-bitENGINE native MTPENGINE f5078d8206 | 32,635 / 1,024 | 75.46 | 26.37 | 1,380.0 | 8/8 | Pass Source, metric, and reviewe9_bench/results/run_20260929_163156/ctx32kENGINE generation rate, including reasoning tokens |
| Qwen3.8-Flash-Next E9 8-bitENGINE native MTPENGINE f5078d8206 | 260,895 / 1,024 | 24.57 | 267.41 | 338.0 | 8/8 | Diagnostic Normal machine conditions Source, metric, and reviewe9_bench/results/run_20260929_163156/ctx256k_aENGINE generation rate, including reasoning tokens |
| Qwen3.8-Flash-Next E9 8-bitENGINE native MTPENGINE f5078d8206 | 260,755 / 1,024 | 24.25 | 684.65 | 338.0 | 8/8 | Diagnostic Normal machine conditions Source, metric, and reviewe9_bench/results/run_20260929_163156/ctx256k_bENGINE generation rate, including reasoning tokens |
| Qwen3.8-Flash-Next E9 8-bitENGINE native MTPENGINE f5078d8206 | 260,895 / 1,024Cached: 260,894 | 59.11 | 0.50 | 923.0 | 8/8 | Diagnostic Normal machine conditions Source, metric, and reviewe9_bench/results/run_20260929_163156/ctx256k_cachedENGINE generation rate, including reasoning tokens |
Early TensorFold Nemotron15 records
Three attempts produced fourteen complete measurements and one interrupted request. The planned full-context matrix remained incomplete.
| Model / mode | Input / output | Decode t/s | First token, s | GPU MHz | Recall | Result / limits |
|---|---|---|---|---|---|---|
| Nemotron Lightning 4-bitMTP + context copiesTensorFold 0.3.6.3 | 32,768 / 1,024 | 160.26 | 16.80 | 1,380.0 | 8/8 | Pass Source, metric, and reviewtensorfold_bench/results/run_20260930_000006/32k_retrieval_1234_draftClient token count and first/last text arrival |
| Nemotron Lightning 4-bitSerialTensorFold 0.3.6.3 | 32,768 / 1,024 | 166.93 | 14.93 | 1,380.0 | 8/8 | Pass Source, metric, and reviewtensorfold_bench/results/run_20260930_000006/32k_retrieval_1234_serialClient token count and first/last text arrival |
| Nemotron Lightning 4-bitMTP + context copiesTensorFold 0.3.6.3 | 2,048 / 256 | 202.29 | 0.97 | 1,331.0 | 8/8 | Diagnostic clock telemetry coverage; at least three decode clock samples Source, metric, and reviewtensorfold_bench/results/run_20260930_000006/short_code_1234_draftClient token count and first/last text arrival |
| Nemotron Lightning 4-bitSerialTensorFold 0.3.6.3 | 2,048 / 256 | 196.86 | 1.06 | 1,332.0 | 8/8 | Diagnostic clock telemetry coverage; at least three decode clock samples Source, metric, and reviewtensorfold_bench/results/run_20260930_000006/short_code_1234_serialClient token count and first/last text arrival |
| Nemotron Lightning 4-bitMTP + context copiesTensorFold 0.3.6.3 | 260,864 / 1,024 | 8.97 | 1,090.06 | 338.0 | 7/8 | Diagnostic cooling gate; median decode clock >=1300 MHz; overall clamp <=5%; decode clamp <=5%; fans >=3400 RPM; load <=8; 8/8 strict retrieval Source, metric, and reviewtensorfold_bench/results/run_20260930_000800/256k_code_1234_draftClient token count and first/last text arrival |
| Nemotron Lightning 4-bitSerialTensorFold 0.3.6.3 | 260,864 / 1,024 | 71.07 | 310.53 | 942.0 | 7/8 | Diagnostic median decode clock >=1300 MHz; 8/8 strict retrieval Source, metric, and reviewtensorfold_bench/results/run_20260930_000800/256k_code_1234_serialClient token count and first/last text arrival |
| Nemotron Lightning 4-bitMTP + context copiesTensorFold 0.3.6.3 | 32,768 / 1,024 | 160.12 | 14.77 | 1,380.0 | 8/8 | Pass Source, metric, and reviewtensorfold_bench/results/run_20260930_000800/32k_retrieval_1234_draftClient token count and first/last text arrival |
| Nemotron Lightning 4-bitSerialTensorFold 0.3.6.3 | 32,768 / 1,024 | 167.09 | 14.94 | 1,380.0 | 8/8 | Pass Source, metric, and reviewtensorfold_bench/results/run_20260930_000800/32k_retrieval_1234_serialClient token count and first/last text arrival |
| Nemotron Lightning 4-bitMTP + context copiesTensorFold 0.3.6.3 | 2,048 / 256 | 237.77 | 0.96 | — | 8/8 | Diagnostic clock telemetry coverage; at least three decode clock samples; median decode clock >=1300 MHz; overall clamp <=5%; decode clamp <=5% Source, metric, and reviewtensorfold_bench/results/run_20260930_000800/short_code_1234_draftClient token count and first/last text arrival |
| Nemotron Lightning 4-bitSerialTensorFold 0.3.6.3 | 2,048 / 256 | 198.32 | 0.83 | 1,380.0 | 8/8 | Diagnostic clock telemetry coverage; at least three decode clock samples Source, metric, and reviewtensorfold_bench/results/run_20260930_000800/short_code_1234_serialClient token count and first/last text arrival |
| Nemotron Lightning 4-bitSerialTensorFold 0.3.6.3 | — / —Requested input: 260,864 | — | 391.22 | — | — | Incomplete stream_completed; prompt_count_matches; cold_prompt; thinking_disabled; draft_mode_matches; draft_activity; token_hash_present; full_output; fan_control_held; median decode clock >=1300 MHz; overall clamp <=5%; decode clamp <=5%; fans >=3400 RPM; load <=8; paired token-hash equality pending or failed; 8/8 strict retrieval Fan control lost: two consecutive readings below 3400 RPM; benchmark server terminated. Source, metric, and reviewtensorfold_bench/results/run_20260930_005309/256k_code_1234_serialClient token count and first/last text arrival |
| Nemotron Lightning 4-bitMTP + context copiesTensorFold 0.3.6.3 | 32,768 / 1,024 | 161.34 | 14.92 | 1,380.0 | 8/8 | Pass Source, metric, and reviewtensorfold_bench/results/run_20260930_005309/32k_retrieval_1234_draftClient token count and first/last text arrival |
| Nemotron Lightning 4-bitSerialTensorFold 0.3.6.3 | 32,768 / 1,024 | 167.36 | 14.91 | 1,380.0 | 8/8 | Pass Source, metric, and reviewtensorfold_bench/results/run_20260930_005309/32k_retrieval_1234_serialClient token count and first/last text arrival |
| Nemotron Lightning 4-bitMTP + context copiesTensorFold 0.3.6.3 | 2,048 / 256 | 255.47 | 0.98 | — | 8/8 | Diagnostic clock telemetry coverage; at least three decode clock samples; median decode clock >=1300 MHz; overall clamp <=5%; decode clamp <=5% Source, metric, and reviewtensorfold_bench/results/run_20260930_005309/short_code_1234_draftClient token count and first/last text arrival |
| Nemotron Lightning 4-bitSerialTensorFold 0.3.6.3 | 2,048 / 256 | 197.95 | 0.83 | — | 8/8 | Diagnostic clock telemetry coverage; at least three decode clock samples; median decode clock >=1300 MHz; overall clamp <=5%; decode clamp <=5% Source, metric, and reviewtensorfold_bench/results/run_20260930_005309/short_code_1234_serialClient token count and first/last text arrival |
Early TensorFold Flash-Next6 records
Six complete measurements with the temperature-1 sampler. The short tests have a smaller output limit.
| Model / mode | Input / output | Decode t/s | First token, s | GPU MHz | Recall | Result / limits |
|---|---|---|---|---|---|---|
| Qwen3.8-Flash-Next 4-bit pilotMTP + context copiesTensorFold 0.3.6.3 | 260,864 / 1,024 | 16.03 | 485.95 | 338.0 | 8/8 | Diagnostic median decode clock >=1300 MHz; overall clamp <=5%; decode clamp <=5% Source, metric, and reviewflashnext_bench/results/run_20260930_115151/256k_retrieval_1234_draftClient token count and first/last text arrival |
| Qwen3.8-Flash-Next 4-bit pilotSerialTensorFold 0.3.6.3 | 260,864 / 1,024 | 16.81 | 273.77 | 338.0 | 8/8 | Diagnostic median decode clock >=1300 MHz; overall clamp <=5%; decode clamp <=5% Source, metric, and reviewflashnext_bench/results/run_20260930_115151/256k_retrieval_1234_serialClient token count and first/last text arrival |
| Qwen3.8-Flash-Next 4-bit pilotMTP + context copiesTensorFold 0.3.6.3 | 32,768 / 1,024 | 96.51 | 27.66 | 1,380.0 | 8/8 | Pass Source, metric, and reviewflashnext_bench/results/run_20260930_115151/32k_retrieval_1234_draftClient token count and first/last text arrival |
| Qwen3.8-Flash-Next 4-bit pilotSerialTensorFold 0.3.6.3 | 32,768 / 1,024 | 76.52 | 27.58 | 1,380.0 | 8/8 | Pass Source, metric, and reviewflashnext_bench/results/run_20260930_115151/32k_retrieval_1234_serialClient token count and first/last text arrival |
| Qwen3.8-Flash-Next 4-bit pilotMTP + context copiesTensorFold 0.3.6.3 | 2,048 / 256 | 104.43 | 2.48 | 1,377.5 | 4/8 | Diagnostic at least three decode clock samples; 8/8 strict retrieval Source, metric, and reviewflashnext_bench/results/run_20260930_115151/short_code_1234_draftClient token count and first/last text arrival |
| Qwen3.8-Flash-Next 4-bit pilotSerialTensorFold 0.3.6.3 | 2,048 / 256 | 76.00 | 2.58 | 1,380.0 | 4/8 | Diagnostic 8/8 strict retrieval Source, metric, and reviewflashnext_bench/results/run_20260930_115151/short_code_1234_serialClient token count and first/last text arrival |
Three GLM-5.3-Flash checkpoints18 records
Eighteen complete measurements. All full-context requests failed the normal machine conditions.
| Model / mode | Input / output | Decode t/s | First token, s | GPU MHz | Recall | Result / limits |
|---|---|---|---|---|---|---|
| GLM-5.3-Flash oQ2MTP + context copiesTensorFold 0.3.6.3 + local compatibility patch | 260,864 / 1,024 | 17.26 | 2,178.46 | 425.0 | 8/8 | Diagnostic median decode clock >=1300 MHz; overall clamp <=5%; decode clamp <=5%; load <=8 Source, metric, and reviewglm53_bench/oq2/results/run_20260930_135359/256k_retrieval_1234_draftClient token count and first/last text arrival |
| GLM-5.3-Flash oQ2SerialTensorFold 0.3.6.3 + local compatibility patch | 260,864 / 1,024 | 12.19 | 2,268.31 | 339.0 | 8/8 | Diagnostic cooling gate; median decode clock >=1300 MHz; overall clamp <=5%; decode clamp <=5%; load <=8 Source, metric, and reviewglm53_bench/oq2/results/run_20260930_135359/256k_retrieval_1234_serialClient token count and first/last text arrival |
| GLM-5.3-Flash oQ2MTP + context copiesTensorFold 0.3.6.3 + local compatibility patch | 32,768 / 1,024 | 76.56 | 78.03 | 1,380.0 | 1/8 | Diagnostic 8/8 strict retrieval Source, metric, and reviewglm53_bench/oq2/results/run_20260930_135359/32k_retrieval_1234_draftClient token count and first/last text arrival |
| GLM-5.3-Flash oQ2SerialTensorFold 0.3.6.3 + local compatibility patch | 32,768 / 1,024 | 30.08 | 86.06 | 1,380.0 | 1/8 | Diagnostic cooling gate; 8/8 strict retrieval Source, metric, and reviewglm53_bench/oq2/results/run_20260930_135359/32k_retrieval_1234_serialClient token count and first/last text arrival |
| GLM-5.3-Flash oQ2MTP + context copiesTensorFold 0.3.6.3 + local compatibility patch | 2,048 / 1,024 | 67.97 | 5.36 | 1,380.0 | 8/8 | Pass Source, metric, and reviewglm53_bench/oq2/results/run_20260930_135359/short_code_1234_draftClient token count and first/last text arrival |
| GLM-5.3-Flash oQ2SerialTensorFold 0.3.6.3 + local compatibility patch | 2,048 / 1,024 | 30.95 | 5.59 | 1,380.0 | 8/8 | Pass Source, metric, and reviewglm53_bench/oq2/results/run_20260930_135359/short_code_1234_serialClient token count and first/last text arrival |
| GLM-5.3-Flash 4-bitMTP + context copiesTensorFold 0.3.6.3 + local compatibility patch | 260,864 / 1,024 | 17.83 | 1,950.06 | 389.0 | 8/8 | Diagnostic median decode clock >=1300 MHz; overall clamp <=5%; decode clamp <=5% Source, metric, and reviewglm53_bench/4bit/results/run_20260930_165827/256k_retrieval_1234_draftClient token count and first/last text arrival |
| GLM-5.3-Flash 4-bitSerialTensorFold 0.3.6.3 + local compatibility patch | 260,864 / 1,024 | 16.15 | 1,961.51 | 338.0 | 8/8 | Diagnostic cooling gate; median decode clock >=1300 MHz; overall clamp <=5%; decode clamp <=5%; load <=8 Source, metric, and reviewglm53_bench/4bit/results/run_20260930_165827/256k_retrieval_1234_serialClient token count and first/last text arrival |
| GLM-5.3-Flash 4-bitMTP + context copiesTensorFold 0.3.6.3 + local compatibility patch | 32,768 / 1,024 | 98.91 | 77.72 | 1,380.0 | 1/8 | Diagnostic 8/8 strict retrieval Source, metric, and reviewglm53_bench/4bit/results/run_20260930_165827/32k_retrieval_1234_draftClient token count and first/last text arrival |
| GLM-5.3-Flash 4-bitSerialTensorFold 0.3.6.3 + local compatibility patch | 32,768 / 1,024 | 40.69 | 77.86 | 1,380.0 | 1/8 | Diagnostic cooling gate; 8/8 strict retrieval Source, metric, and reviewglm53_bench/4bit/results/run_20260930_165827/32k_retrieval_1234_serialClient token count and first/last text arrival |
| GLM-5.3-Flash 4-bitMTP + context copiesTensorFold 0.3.6.3 + local compatibility patch | 2,048 / 1,024 | 51.48 | 5.79 | 1,380.0 | 8/8 | Pass Source, metric, and reviewglm53_bench/4bit/results/run_20260930_165827/short_code_1234_draftClient token count and first/last text arrival |
| GLM-5.3-Flash 4-bitSerialTensorFold 0.3.6.3 + local compatibility patch | 2,048 / 1,024 | 42.19 | 5.78 | 1,380.0 | 8/8 | Pass Source, metric, and reviewglm53_bench/4bit/results/run_20260930_165827/short_code_1234_serialClient token count and first/last text arrival |
| GLM-5.3-Flash oQ4MTP + context copiesTensorFold 0.3.6.3 + local compatibility patch | 260,864 / 1,024 | 16.23 | 1,952.06 | 353.5 | 8/8 | Diagnostic median decode clock >=1300 MHz; overall clamp <=5%; decode clamp <=5% Source, metric, and reviewglm53_bench/oq4/results/run_20260930_195227/256k_retrieval_1234_draftClient token count and first/last text arrival |
| GLM-5.3-Flash oQ4SerialTensorFold 0.3.6.3 + local compatibility patch | 260,864 / 1,024 | 13.26 | 1,945.40 | 338.0 | 8/8 | Diagnostic median decode clock >=1300 MHz; overall clamp <=5%; decode clamp <=5%; load <=8 Source, metric, and reviewglm53_bench/oq4/results/run_20260930_195227/256k_retrieval_1234_serialClient token count and first/last text arrival |
| GLM-5.3-Flash oQ4MTP + context copiesTensorFold 0.3.6.3 + local compatibility patch | 32,768 / 1,024 | 86.12 | 77.69 | 1,380.0 | 1/8 | Diagnostic 8/8 strict retrieval Source, metric, and reviewglm53_bench/oq4/results/run_20260930_195227/32k_retrieval_1234_draftClient token count and first/last text arrival |
| GLM-5.3-Flash oQ4SerialTensorFold 0.3.6.3 + local compatibility patch | 32,768 / 1,024 | 33.42 | 80.50 | 1,380.0 | 1/8 | Diagnostic cooling gate; 8/8 strict retrieval Source, metric, and reviewglm53_bench/oq4/results/run_20260930_195227/32k_retrieval_1234_serialClient token count and first/last text arrival |
| GLM-5.3-Flash oQ4MTP + context copiesTensorFold 0.3.6.3 + local compatibility patch | 2,048 / 1,024 | 46.78 | 5.72 | 1,380.0 | 8/8 | Pass Source, metric, and reviewglm53_bench/oq4/results/run_20260930_195227/short_code_1234_draftClient token count and first/last text arrival |
| GLM-5.3-Flash oQ4SerialTensorFold 0.3.6.3 + local compatibility patch | 2,048 / 1,024 | 34.20 | 5.74 | 1,380.0 | 8/8 | Pass Source, metric, and reviewglm53_bench/oq4/results/run_20260930_195227/short_code_1234_serialClient token count and first/last text arrival |
GLM-5.3-Flash with TensorFold 0.6.534 records
All thirty-four attempts ended: twenty requests completed, and fourteen attempts failed. The tests used a greedy sampler and a fresh server for each request.
| Model / mode | Input / output | Decode t/s | First token, s | GPU MHz | Recall | Result / limits |
|---|---|---|---|---|---|---|
| GLM-5.3-Flash 4-bittensorfold_serialTensorFold 0.6.5 | — / —Requested input: 2,048 | — | — | — | — | Incomplete TimeoutError('TensorFold startup exceeded 1440 seconds') Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261005_142827/glm_4bit_2048_1234_tensorfold_serial_0Output token slope after token 32 |
| GLM-5.3-Flash 4-bittensorfold_mtpTensorFold 0.6.5 | 2,048 / 1,024 | 52.08 | 5.03 | 1,380.0 | 8/8 | Pass Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261005_145619/glm_4bit_2048_1234_tensorfold_mtp_1Output token slope after token 32 Host weight read: 13.60 s, outside the first-token time. The output bytes equal the manually reviewed serial output.All 1024 tokens match the serial control.All eight answer records match the input.The same guide limitation applies: one quoted filler sentence is absent from the input.This review does not validate every guide claim. |
| GLM-5.3-Flash 4-bittensorfold_serialTensorFold 0.6.5 | 2,048 / 1,024 | 42.69 | 5.14 | 1,380.0 | 8/8 | Pass Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261005_145619/glm_4bit_2048_1234_tensorfold_serial_0Output token slope after token 32 Host weight read: 1,557.53 s, outside the first-token time. All eight answer records match the input.The output contains no visible repetition loop.The guide ends at the 1024-token output limit.One quoted filler sentence does not occur in the input.The Nakhodka context description agrees with the input.This review does not validate every guide claim. |
| GLM-5.3-Flash 4-bittensorfold_mtpTensorFold 0.6.5 | 260,864 / 1,024 | 19.21 | 1,228.41 | 397.0 | 8/8 | Diagnostic normal_decode_clock; decode_clamp; load Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261005_145619/glm_4bit_260864_1234_tensorfold_mtp_5Output token slope after token 32 Host weight read: 1,161.34 s, outside the first-token time. The output bytes equal the manually reviewed full-context serial output.All 1024 tokens match the serial control.All eight answer records match the input.The same imprecise sentence-count description remains in the guide.This review does not validate every guide claim. |
| GLM-5.3-Flash 4-bittensorfold_cooled_prefill_mtpTensorFold 0.6.5 | 260,864 / 1,024 | 44.54 | 1,355.33 | 1,380.0 | 8/8 | Diagnostic load Pause: 251.02 s Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261005_145619/glm_4bit_260864_1234_tensorfold_mtp_7Output token slope after token 32 Host weight read: 1,917.62 s, outside the first-token time. The answer bytes, prompt IDs, and all 1024 output tokens equal the reviewed serial pause control.All eight answer records match the full input.The output contains no visible repetition loop.The guide ends at the 1024-token output limit.The described Reykjavik context agrees with the nearby cistern sentences.The guide describes hundreds of sentences, although the prompt contains 13867 full stops.This review does not validate every guide claim. |
| GLM-5.3-Flash 4-bittensorfold_serialTensorFold 0.6.5 | 260,864 / 1,024 | 14.23 | 1,328.49 | 338.0 | 8/8 | Diagnostic normal_decode_clock; decode_clamp Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261005_145619/glm_4bit_260864_1234_tensorfold_serial_4Output token slope after token 32 Host weight read: 14.77 s, outside the first-token time. All eight answer records match the full input.The output contains no visible repetition loop.The guide ends at the 1024-token output limit.The described Reykjavik context agrees with the nearby cistern sentences.The guide describes hundreds of sentences, although the prompt contains 13867 full stops.This review does not validate every guide claim. |
| GLM-5.3-Flash 4-bittensorfold_cooled_prefill_serialTensorFold 0.6.5 | 260,864 / 1,024 | 38.49 | 1,580.54 | 1,380.0 | 8/8 | Pass Pause: 255.88 s Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261005_145619/glm_4bit_260864_1234_tensorfold_serial_6Output token slope after token 32 Host weight read: 439.83 s, outside the first-token time. The answer bytes, prompt IDs, and output tokens equal the reviewed full-context serial control.All eight answer records match the full input.The output contains no visible repetition loop.The guide ends at the 1024-token output limit.The described Reykjavik context agrees with the nearby cistern sentences.The guide describes hundreds of sentences, although the prompt contains 13867 full stops.This review does not validate every guide claim. |
| GLM-5.3-Flash 4-bittensorfold_mtpTensorFold 0.6.5 | 32,768 / 1,024 | 51.54 | 58.83 | 1,380.0 | 8/8 | Pass Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261005_145619/glm_4bit_32768_1234_tensorfold_mtp_3Output token slope after token 32 Host weight read: 15.05 s, outside the first-token time. The output bytes equal the manually reviewed serial output.All 1024 tokens match the serial control.All eight answer records match the input.The same incorrect position and context claims remain in the guide.The narrow retrieval pass does not validate the guide. |
| GLM-5.3-Flash 4-bittensorfold_serialTensorFold 0.6.5 | 32,768 / 1,024 | 41.51 | 58.99 | 1,380.0 | 8/8 | Pass Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261005_145619/glm_4bit_32768_1234_tensorfold_serial_2Output token slope after token 32 Host weight read: 14.22 s, outside the first-token time. All eight answer records match the input.The output contains no visible repetition loop.The guide ends at the 1024-token output limit.The guide places the Reykjavik record at one-fifth of the document. Its actual character position is about 2.9 percent.The guide gives two different descriptions of the Reykjavik context. Only the brittle-trellis description matches the input.The narrow retrieval pass does not validate the guide. |
| GLM-5.3-Flash oQ4tensorfold_serialTensorFold 0.6.5 | — / —Requested input: 2,048 | — | — | — | — | Incomplete RuntimeError('TensorFold exited with code 1') Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261005_145619/glm_oq4_2048_1234_tensorfold_serial_8Output token slope after token 32 Host weight read: 2,213.55 s, outside the first-token time. Startup error: RuntimeError: [METAL] Command buffer execution failed: Caused GPU Timeout Error (00000002:kIOGPUCommandBufferCallbackErrorTimeout). |
| GLM-5.3-Flash oQ4tensorfold_mtpTensorFold 0.6.5 | — / —Requested input: 2,048 | — | — | — | — | Incomplete KeyboardInterrupt('signal 15') The agent stopped the host read before the model server or measured request started. Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261005_200547/glm_oq4_2048_1234_tensorfold_mtp_1Output token slope after token 32 |
| GLM-5.3-Flash oQ4tensorfold_serialTensorFold 0.6.5 | 2,048 / 1,024 | 34.28 | 5.51 | 1,380.0 | 8/8 | Pass Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261005_200547/glm_oq4_2048_1234_tensorfold_serial_0Output token slope after token 32 Host weight read: 2,082.45 s, outside the first-token time. All eight answer records match the input, in the requested order.The output contains no visible repetition loop.The guide ends at the 1024-token output limit.The quoted distant-belfry text occurs at the start of the archive.The guide gives incorrect filler-sentence positions for Timbuktu, Kirkwall, Ushuaia, and Yakutsk.Their original filler-sentence positions are 14, 17, 20, and 24, rather than 15, 18, 22, and 26.This review does not validate every guide claim. |
| GLM-5.3-Flash oQ4tensorfold_mtpTensorFold 0.6.5 | 2,048 / 1,024 | 46.54 | 5.17 | 1,380.0 | 8/8 | Pass Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261005_213646/glm_oq4_2048_1234_tensorfold_mtp_1Output token slope after token 32 The answer bytes, prompt IDs, and all 1024 output tokens equal the reviewed direct-load serial control.All eight answer records match the input, in the requested order.The output contains no visible repetition loop.The guide ends at the 1024-token output limit.The quoted distant-belfry text occurs at the start of the archive.The guide gives incorrect filler-sentence positions for Timbuktu, Kirkwall, Ushuaia, and Yakutsk.Their original filler-sentence positions are 14, 17, 20, and 24, rather than 15, 18, 22, and 26.This review does not validate every guide claim. |
| GLM-5.3-Flash oQ4tensorfold_serialTensorFold 0.6.5 | 2,048 / 1,024 | 34.50 | 5.21 | 1,380.0 | 8/8 | Pass Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261005_213646/glm_oq4_2048_1234_tensorfold_serial_0Output token slope after token 32 Exact reference match: Yes. glm53_tensorfold065_bench/results/run_20261005_200547/glm_oq4_2048_1234_tensorfold_serial_0 The answer bytes, prompt IDs, and all 1024 output tokens equal the reviewed serial control with the separate host read.All eight answer records match the input, in the requested order.The output contains no visible repetition loop.The guide ends at the 1024-token output limit.The quoted distant-belfry text occurs at the start of the archive.The guide gives incorrect filler-sentence positions for Timbuktu, Kirkwall, Ushuaia, and Yakutsk.Their original filler-sentence positions are 14, 17, 20, and 24, rather than 15, 18, 22, and 26.This review does not validate every guide claim. |
| GLM-5.3-Flash oQ4tensorfold_mtpTensorFold 0.6.5 | 260,864 / 1,024 | 14.59 | 1,225.57 | 343.0 | 8/8 | Diagnostic normal_decode_clock; decode_clamp; matched_serial_exactness MTP control unavailable: The serial control did not complete Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261005_213646/glm_oq4_260864_1234_tensorfold_mtp_5Output token slope after token 32 All eight answer records match the input, in the requested order.The output contains no visible repetition loop.The guide ends at the 1024-token output limit.Both quoted filler sentences occur in the input.The described Reykjavik context and its quoted continuation agree with the input.The guide starts a second record list as an extraction example.This review does not validate every guide claim.The baseline serial request did not complete, so the paired exactness check remains unavailable. |
| GLM-5.3-Flash oQ4tensorfold_serialTensorFold 0.6.5 | — / —Requested input: 260,864Last reported prefill: 131,072 | — | — | — | — | Incomplete KeyboardInterrupt('signal 15') System load exceeded16 twice Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261005_213646/glm_oq4_260864_1234_tensorfold_serial_4Output token slope after token 32 |
| GLM-5.3-Flash oQ4tensorfold_cooled_prefill_serialTensorFold 0.6.5 | — / —Requested input: 260,864 | — | — | — | — | Incomplete RuntimeError('TensorFold exited with code 1') Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261005_213646/glm_oq4_260864_1234_tensorfold_serial_6Output token slope after token 32 Startup error: RuntimeError: [METAL] Command buffer execution failed: Caused GPU Timeout Error (00000002:kIOGPUCommandBufferCallbackErrorTimeout). |
| GLM-5.3-Flash oQ4tensorfold_mtpTensorFold 0.6.5 | 32,768 / 1,024 | 46.66 | 60.89 | 1,380.0 | 8/8 | Pass Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261005_213646/glm_oq4_32768_1234_tensorfold_mtp_3Output token slope after token 32 The answer bytes, prompt IDs, and all 1024 output tokens equal the reviewed serial control.All eight answer records match the input, in the requested order.The output contains no visible repetition loop.The guide ends at the 1024-token output limit.The quoted Reykjavik sentence appears verbatim in the input.The guide describes hundreds of sentences, although the prompt contains 1680 full stops.This review does not validate every guide claim. |
| GLM-5.3-Flash oQ4tensorfold_serialTensorFold 0.6.5 | 32,768 / 1,024 | 33.77 | 61.04 | 1,380.0 | 8/8 | Pass Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261005_213646/glm_oq4_32768_1234_tensorfold_serial_2Output token slope after token 32 All eight answer records match the input, in the requested order.The output contains no visible repetition loop.The guide ends at the 1024-token output limit.The quoted Reykjavik sentence appears verbatim in the input.The guide describes hundreds of sentences, although the prompt contains 1680 full stops.This review does not validate every guide claim. |
| GLM-5.3-Flash oQ4tensorfold_serialTensorFold 0.6.5 | — / —Requested input: 260,864 | — | — | — | — | Incomplete RuntimeError('TensorFold exited with code 1') Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261005_230806/glm_oq4_260864_1234_tensorfold_serial_0Output token slope after token 32 Startup error: RuntimeError: [METAL] Command buffer execution failed: Caused GPU Timeout Error (00000002:kIOGPUCommandBufferCallbackErrorTimeout). |
| GLM-5.3-Flash oQ2tensorfold_serialTensorFold 0.6.5 | — / —Requested input: 2,048 | — | — | — | — | Incomplete RuntimeError('TensorFold exited with code 1') Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261005_232901/glm_oq2_2048_1234_tensorfold_serial_0Output token slope after token 32 Startup error: RuntimeError: [METAL] Command buffer execution failed: Caused GPU Timeout Error (00000002:kIOGPUCommandBufferCallbackErrorTimeout). |
| GLM-5.3-Flash oQ4tensorfold_eager_load_serialTensorFold 0.6.5 | 2,048 / 1,024 | 34.54 | 5.68 | 1,380.0 | 8/8 | Pass Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261005_234048/glm_oq4_2048_1234_tensorfold_serial_0Output token slope after token 32 Model loader: 3,261.61 s, outside the first-token time. Exact reference match: Yes. glm53_tensorfold065_bench/results/run_20261005_213646/glm_oq4_2048_1234_tensorfold_serial_0 The answer bytes, prompt IDs, and all 1024 output tokens equal the reviewed serial control with the separate host read.All eight answer records match the input, in the requested order.The output contains no visible repetition loop.The guide ends at the 1024-token output limit.The quoted distant-belfry text occurs at the start of the archive.The guide gives incorrect filler-sentence positions for Timbuktu, Kirkwall, Ushuaia, and Yakutsk.Their original filler-sentence positions are 14, 17, 20, and 24, rather than 15, 18, 22, and 26.This review does not validate every guide claim. |
| GLM-5.3-Flash oQ4tensorfold_eager_load_serialTensorFold 0.6.5 | — / —Requested input: 260,864Last reported prefill: 212,992 | — | — | — | — | Incomplete KeyboardInterrupt('signal 15') The driver received SIGHUP after the assistant service restart. Its cleanup sent SIGTERM to the active campaign and worker. Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261005_234048/glm_oq4_260864_1234_tensorfold_serial_2Output token slope after token 32 Model loader: 3,266.54 s, outside the first-token time. |
| GLM-5.3-Flash oQ4tensorfold_eager_load_serialTensorFold 0.6.5 | 32,768 / 1,024 | 33.70 | 61.15 | 1,380.0 | 8/8 | Pass Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261005_234048/glm_oq4_32768_1234_tensorfold_serial_1Output token slope after token 32 Model loader: 2,883.17 s, outside the first-token time. Exact reference match: Yes. glm53_tensorfold065_bench/results/run_20261005_213646/glm_oq4_32768_1234_tensorfold_serial_2 All eight answer records match the input, in the requested order.The output contains no visible repetition loop.The guide ends at the 1024-token output limit.The quoted Reykjavik sentence appears verbatim in the input.The guide describes hundreds of sentences, although the prompt contains 1680 full stops.This review does not validate every guide claim. |
| GLM-5.3-Flash oQ2tensorfold_eager_load_mtpTensorFold 0.6.5 | 2,048 / 1,024 | 39.86 | 4.72 | 1,380.0 | 8/8 | Pass Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261006_025508/glm_oq2_2048_1234_tensorfold_mtp_3Output token slope after token 32 Model loader: 1,105.61 s, outside the first-token time. All eight answer records match the input, in the requested order.The output contains no visible repetition loop.The quoted opening fragment occurs in the input.The Reykjavik example correctly identifies the first record and its immediate context.The guide ends at the 1024-token output limit.This review does not validate every guide claim. |
| GLM-5.3-Flash oQ2tensorfold_eager_load_serialTensorFold 0.6.5 | 2,048 / 1,024 | 31.06 | 5.30 | 1,380.0 | 8/8 | Pass Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261006_025508/glm_oq2_2048_1234_tensorfold_serial_2Output token slope after token 32 Model loader: 2,034.87 s, outside the first-token time. All eight answer records match the input, in the requested order.The output contains no visible repetition loop.The quoted opening fragment occurs in the input.The Reykjavik example correctly identifies the first record and its immediate context.The guide ends at the 1024-token output limit.This review does not validate every guide claim. |
| GLM-5.3-Flash oQ2tensorfold_eager_load_mtpTensorFold 0.6.5 | — / —Requested input: 260,864Last reported prefill: 114,688 | — | — | — | — | Incomplete KeyboardInterrupt('signal 15') System load exceeded16 twice Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261006_025508/glm_oq2_260864_1234_tensorfold_mtp_7Output token slope after token 32 Model loader: 71.93 s, outside the first-token time. |
| GLM-5.3-Flash oQ2tensorfold_eager_load_serialTensorFold 0.6.5 | — / —Requested input: 260,864Last reported prefill: 114,688 | — | — | — | — | Incomplete KeyboardInterrupt('signal 15') System load exceeded16 twice Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261006_025508/glm_oq2_260864_1234_tensorfold_serial_6Output token slope after token 32 Model loader: 46.87 s, outside the first-token time. |
| GLM-5.3-Flash oQ2tensorfold_eager_load_mtpTensorFold 0.6.5 | 32,768 / 1,024 | 46.21 | 64.92 | 1,380.0 | 8/8 | Pass Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261006_025508/glm_oq2_32768_1234_tensorfold_mtp_5Output token slope after token 32 Model loader: 236.83 s, outside the first-token time. All eight answer records match the input, in the requested order.The output contains no visible repetition loop.The five complete quoted record examples match the input.The partial Kirkwall example also matches the input before the output ends.The Timbuktu record occurs after the complete phrase faded near; it does not split that phrase itself.The stated common insertion position does not describe every record.The guide says hundreds of sentences; the archive contains 1,669 full stops.The guide ends at the 1024-token output limit.This review does not validate every guide claim. |
| GLM-5.3-Flash oQ2tensorfold_eager_load_serialTensorFold 0.6.5 | 32,768 / 1,024 | 30.54 | 64.93 | 1,380.0 | 8/8 | Pass Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261006_025508/glm_oq2_32768_1234_tensorfold_serial_4Output token slope after token 32 Model loader: 161.95 s, outside the first-token time. All eight answer records match the input, in the requested order.The output contains no visible repetition loop.The five complete quoted record examples match the input.The partial Kirkwall example also matches the input before the output ends.The Timbuktu record occurs after the complete phrase faded near; it does not split that phrase itself.The stated common insertion position does not describe every record.The guide says hundreds of sentences; the archive contains 1,669 full stops.The guide ends at the 1024-token output limit.This review does not validate every guide claim. |
| GLM-5.3-Flash oQ4tensorfold_eager_load_mtpTensorFold 0.6.5 | — / —Requested input: 260,864Last reported prefill: 163,840 | — | — | — | — | Incomplete KeyboardInterrupt('signal 15') System load exceeded16 twice Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261006_025508/glm_oq4_260864_1234_tensorfold_mtp_1Output token slope after token 32 Model loader: 2,308.66 s, outside the first-token time. |
| GLM-5.3-Flash oQ4tensorfold_eager_load_serialTensorFold 0.6.5 | — / —Requested input: 260,864Last reported prefill: 163,840 | — | — | — | — | Incomplete KeyboardInterrupt('signal 15') System load exceeded16 twice Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261006_025508/glm_oq4_260864_1234_tensorfold_serial_0Output token slope after token 32 Model loader: 2,445.67 s, outside the first-token time. |
| GLM-5.3-Flash oQ4tensorfold_eager_load_cooled_prefill_serialTensorFold 0.6.5 | — / —Requested input: 260,864 | — | — | — | — | Incomplete TimeoutError('TensorFold startup exceeded 3600 seconds') Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261006_063141/glm_oq4_260864_1234_tensorfold_serial_0Output token slope after token 32 Startup error: TimeoutError('TensorFold startup exceeded 3600 seconds') |
| GLM-5.3-Flash oQ4tensorfold_eager_load_cooled_prefill_mtpTensorFold 0.6.5 | — / —Requested input: 260,864Last reported prefill: 163,840 | — | — | — | — | Incomplete Background intervention: 2 searches ended during this request, after 163,840 reported prefill tokens. The user authorized both terminations during this request. This change prevents a comparison under identical background conditions. KeyboardInterrupt('signal 15') System load exceeded16 twice Source, metric, and reviewglm53_tensorfold065_bench/results/run_20261006_073714/glm_oq4_260864_1234_tensorfold_mtp_0Output token slope after token 32 Model loader: 2,264.20 s, outside the first-token time. |
Exact Ollama Qwen3.8-27B12 records
Eight complete short-context requests and four interrupted full-context requests. Both Metal backends remain separate.
| Model / mode | Input / output | Decode t/s | First token, s | GPU MHz | Recall | Result / limits |
|---|---|---|---|---|---|---|
| qwen3.8:27b-mlx NVFP4mlx_metal_v4Ollama / mlx_metal_v4 0.35.0 | — / —Requested input: 260,864 | — | — | — | — | Incomplete cooling_gate; decode_clock; decode_clamp; overall_clamp; load KeyboardInterrupt('signal15') Source, metric, and reviewqwen38_27b_bench/results/run_20261001_173331/256k_rep1/result.jsonClient output token slope |
| qwen3.8:27b-mlx NVFP4mlx_metal_v4Ollama / mlx_metal_v4 0.35.0 | 2,048 / 1,024 | 88.86 | 5.28 | 1,380.0 | 8/8 | Pass Source, metric, and reviewqwen38_27b_bench/results/run_20261001_173331/2k_rep1/result.jsonClient output token slope |
| qwen3.8:27b-mlx NVFP4mlx_metal_v4Ollama / mlx_metal_v4 0.35.0 | 2,048 / 1,024 | 82.24 | 4.86 | 1,380.0 | 8/8 | Pass Source, metric, and reviewqwen38_27b_bench/results/run_20261001_173331/2k_rep2/result.jsonClient output token slope |
| qwen3.8:27b-mlx NVFP4mlx_metal_v4Ollama / mlx_metal_v4 0.35.0 | 32,768 / 1,024 | 45.67 | 86.01 | 1,380.0 | 8/8 | Pass Source, metric, and reviewqwen38_27b_bench/results/run_20261001_173331/32k_rep1/result.jsonClient output token slope |
| qwen3.8:27b-mlx NVFP4mlx_metal_v4Ollama / mlx_metal_v4 0.35.0 | 32,768 / 1,024 | 48.67 | 85.98 | 1,380.0 | 8/8 | Pass Source, metric, and reviewqwen38_27b_bench/results/run_20261001_173331/32k_rep2/result.jsonClient output token slope |
| qwen3.8:27b-mlx NVFP4mlx_metal_v4Ollama / mlx_metal_v4 0.35.0 | — / —Requested input: 260,864 | — | — | — | — | Incomplete decode_clock; decode_clamp; overall_clamp; load Two consecutive system-load readings above16 Source, metric, and reviewqwen38_27b_bench/results/run_20261001_180533/256k_rep1/result.jsonClient output token slope |
| qwen3.8:27b-mlx NVFP4mlx_metal_v4Ollama / mlx_metal_v4 0.35.0 | — / —Requested input: 260,864 | — | — | — | — | Incomplete decode_clock; decode_clamp; overall_clamp; load Two consecutive system-load readings above16 Source, metric, and reviewqwen38_27b_bench/results/run_20261001_182755/256k_rep1/result.jsonClient output token slope |
| qwen3.8:27b-mlx NVFP4mlx_metal_v3Ollama / mlx_metal_v3 0.35.0 | — / —Requested input: 260,864 | — | — | — | — | Incomplete decode_clock; decode_clamp; overall_clamp; load Two consecutive system-load readings above16 Source, metric, and reviewqwen38_27b_bench/results/run_20261001_184030/256k_rep1/result.jsonClient output token slope |
| qwen3.8:27b-mlx NVFP4mlx_metal_v3Ollama / mlx_metal_v3 0.35.0 | 2,048 / 1,024 | 85.55 | 5.41 | 1,380.0 | 8/8 | Pass Source, metric, and reviewqwen38_27b_bench/results/run_20261001_184030/2k_rep1/result.jsonClient output token slope |
| qwen3.8:27b-mlx NVFP4mlx_metal_v3Ollama / mlx_metal_v3 0.35.0 | 2,048 / 1,024 | 80.69 | 4.86 | 1,380.0 | 8/8 | Pass Source, metric, and reviewqwen38_27b_bench/results/run_20261001_184030/2k_rep2/result.jsonClient output token slope |
| qwen3.8:27b-mlx NVFP4mlx_metal_v3Ollama / mlx_metal_v3 0.35.0 | 32,768 / 1,024 | 48.29 | 86.00 | 1,380.0 | 8/8 | Pass Source, metric, and reviewqwen38_27b_bench/results/run_20261001_184030/32k_rep1/result.jsonClient output token slope |
| qwen3.8:27b-mlx NVFP4mlx_metal_v3Ollama / mlx_metal_v3 0.35.0 | 32,768 / 1,024 | 48.31 | 86.05 | 1,380.0 | 8/8 | Pass Source, metric, and reviewqwen38_27b_bench/results/run_20261001_184030/32k_rep2/result.jsonClient output token slope |
Eight-model campaign and follow-up tests63 records
All sixty-three attempts from the final combined report. The records include cache variants, accelerator checks, and prefill pauses.
| Model / mode | Input / output | Decode t/s | First token, s | GPU MHz | Recall | Result / limits |
|---|---|---|---|---|---|---|
| Gemma 4 26B-A4B QAT 4-bitserialmlx-lm 0.32.1.dev4+g53b9af378 | 2,048 / 1,024 | 102.15 | 0.92 | 1,380.0 | 8/8 | Pass Source, metric, and revieweight_models_bench/results/run_20261002_122104/gemma26_2048_1234Output token slope after token 32 |
| Gemma 4 26B-A4B QAT 4-bitserialmlx-lm 0.32.1.dev4+g53b9af378 | 260,864 / 1,024 | 11.17 | 870.12 | 511.0 | 2/8 | Diagnostic normal_decode_clock; load The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_122104/gemma26_260864_1234Output token slope after token 32 |
| Gemma 4 26B-A4B QAT 4-bitserialmlx-lm 0.32.1.dev4+g53b9af378 | 32,768 / 1,024 | 71.48 | 16.15 | 1,380.0 | 6/8 | Diagnostic The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_122104/gemma26_32768_1234Output token slope after token 32 |
| MiMo-V2.6-Distill-Qwen-9B mixed 4/6-bitserialmlx-lm 0.32.1.dev4+g53b9af378 | 2,048 / 1,024 | 98.98 | 1.33 | 1,380.0 | 8/8 | Pass Source, metric, and revieweight_models_bench/results/run_20261002_122104/mimo9_2048_1234Output token slope after token 32 |
| MiMo-V2.6-Distill-Qwen-9B mixed 4/6-bitserialmlx-lm 0.32.1.dev4+g53b9af378 | — / —Requested input: 260,864 | — | — | — | — | Incomplete KeyboardInterrupt('signal 15') Source, metric, and revieweight_models_bench/results/run_20261002_122104/mimo9_260864_1234Output token slope after token 32 |
| MiMo-V2.6-Distill-Qwen-9B mixed 4/6-bitserialmlx-lm 0.32.1.dev4+g53b9af378 | 32,768 / 1,024 | 82.52 | 23.57 | 1,380.0 | 8/8 | Pass Source, metric, and revieweight_models_bench/results/run_20261002_122104/mimo9_32768_1234Output token slope after token 32 |
| Qwen3.5-2B 4-bitserialmlx-lm 0.32.1.dev4+g53b9af378 | — / —Requested input: 2,048 | — | — | — | — | Incomplete RuntimeError('Required cool/quiet gate failed; no timed inference') Source, metric, and revieweight_models_bench/results/run_20261002_122104/qwen2_2048_1234Output token slope after token 32 |
| Qwen3.5-2B 4-bitserialmlx-lm 0.32.1.dev4+g53b9af378 | 2,048 / 1,024 | 275.07 | 0.31 | 1,380.0 | 8/8 | Diagnostic The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_122104/qwen2_2048_1234_mlx-lm_serial_0Output token slope after token 32 |
| Qwen3.5-2B 4-bitserialmlx-lm 0.32.1.dev4+g53b9af378 | 260,864 / 1,024 | 82.38 | 134.67 | 1,380.0 | 8/8 | Pass Source, metric, and revieweight_models_bench/results/run_20261002_122104/qwen2_260864_1234_mlx-lm_serial_2Output token slope after token 32 |
| Qwen3.5-2B 4-bitserialmlx-lm 0.32.1.dev4+g53b9af378 | 260,864 / 1,024 | 82.59 | 134.24 | 1,380.0 | 0/8 | Diagnostic The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_122104/qwen2_260864_1235_mlx-lm_serial_3Output token slope after token 32 |
| Qwen3.5-2B 4-bitserialmlx-lm 0.32.1.dev4+g53b9af378 | 260,864 / 1,024 | 82.43 | 134.41 | 1,380.0 | 8/8 | Diagnostic The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_122104/qwen2_260864_1236_mlx-lm_serial_4Output token slope after token 32 |
| Qwen3.5-2B 4-bitserialmlx-lm 0.32.1.dev4+g53b9af378 | 32,768 / 1,024 | 215.48 | 5.76 | 1,380.0 | 0/8 | Diagnostic The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_122104/qwen2_32768_1234_mlx-lm_serial_1Output token slope after token 32 |
| Spark-X2.5-1.7B protected 8-bitserialmlx-lm 0.32.1.dev4+g53b9af378 | 2,048 / 1,024 | 196.05 | 0.41 | 1,380.0 | 0/8 | Diagnostic The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_122104/spark17_2048_1234Output token slope after token 32 |
| Spark-X2.5-1.7B protected 8-bitserialmlx-lm 0.32.1.dev4+g53b9af378 | 260,864 / 1,024 | 66.58 | 158.46 | 1,380.0 | 0/8 | Diagnostic The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_122104/spark17_260864_1234Output token slope after token 32 |
| Spark-X2.5-1.7B protected 8-bitserialmlx-lm 0.32.1.dev4+g53b9af378 | 32,768 / 1,024 | 158.63 | 6.75 | 1,380.0 | 0/8 | Diagnostic The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_122104/spark17_32768_1234Output token slope after token 32 |
| Spark-X2.5-4B 8-bitserialmlx-lm 0.32.1.dev4+g53b9af378 | 2,048 / 1,024 | 103.06 | 0.84 | 1,380.0 | 8/8 | Pass Source, metric, and revieweight_models_bench/results/run_20261002_122104/spark4_2048_1234Output token slope after token 32 |
| Spark-X2.5-4B 8-bitserialmlx-lm 0.32.1.dev4+g53b9af378 | 260,864 / 1,024 | 15.61 | 987.60 | 338.0 | 8/8 | Diagnostic normal_decode_clock; decode_clamp; unmodified_execution Source, metric, and revieweight_models_bench/results/run_20261002_122104/spark4_260864_1234Output token slope after token 32 |
| Spark-X2.5-4B 8-bitserialmlx-lm 0.32.1.dev4+g53b9af378 | 32,768 / 1,024 | 83.81 | 16.50 | 1,380.0 | 7/8 | Diagnostic The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_122104/spark4_32768_1234Output token slope after token 32 |
| KAT-Coder-V2.5-Dev OptiQ 4-bitserialmlx-lm 0.32.1.dev4+g53b9af378 | 2,048 / 1,024 | 86.83 | 0.86 | 1,380.0 | 8/8 | Pass Source, metric, and revieweight_models_bench/results/run_20261002_143653/kat35_2048_1234_mlx-lm_serial_0Output token slope after token 32 |
| KAT-Coder-V2.5-Dev OptiQ 4-bitserialmlx-lm 0.32.1.dev4+g53b9af378 | — / —Requested input: 260,864 | — | — | — | — | Incomplete KeyboardInterrupt('signal 15') Source, metric, and revieweight_models_bench/results/run_20261002_143653/kat35_260864_1234_mlx-lm_serial_2Output token slope after token 32 |
| KAT-Coder-V2.5-Dev OptiQ 4-bitserialmlx-lm 0.32.1.dev4+g53b9af378 | 32,768 / 1,024 | 76.72 | 14.87 | 1,380.0 | 8/8 | Pass Source, metric, and revieweight_models_bench/results/run_20261002_143653/kat35_32768_1234_mlx-lm_serial_1Output token slope after token 32 |
| North-Mini-Code-1.0 4-bitserialmlx-lm + mlx-vlm model 0.32.1.dev4+g53b9af378 | 2,048 / 1,024 | 88.38 | 0.93 | 1,380.0 | 0/8 | Diagnostic The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_145828/north30_2048_1234_mlx-lm_serial_0Output token slope after token 32 |
| North-Mini-Code-1.0 4-bitserialmlx-lm + mlx-vlm model 0.32.1.dev4+g53b9af378 | — / —Requested input: 260,864 | — | — | — | — | Incomplete KeyboardInterrupt('signal 15') Source, metric, and revieweight_models_bench/results/run_20261002_145828/north30_260864_1234_mlx-lm_serial_2Output token slope after token 32 |
| North-Mini-Code-1.0 4-bitserialmlx-lm + mlx-vlm model 0.32.1.dev4+g53b9af378 | 32,768 / 1,024 | 78.80 | 20.32 | 1,380.0 | 0/8 | Diagnostic The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_145828/north30_32768_1234_mlx-lm_serial_1Output token slope after token 32 |
| Ling-3.0-flash 4-bitserialmlx-lm 0.32.1.dev4+g53b9af378 | — / —Requested input: 2,048 | — | — | — | — | Incomplete ValueError('Received 225 parameters not in model: \nmodel.layers.0.attention.k_conv1d.conv.weight,\nmodel.layers.0.attention.q_conv1d.conv.weight,\nmodel.layers.0.attention.v_conv1d.conv.weight,\nmodel.layers.1.attention.k_conv1d.conv.weight,\nmodel.layers.1.attention.q_conv1d.conv.weight,\nmodel.layers.1.attention.v_conv1d.conv.weight,\nmodel.layers.10.attention.k_conv1d.conv.weight,\nmodel.layers.10.attention.q_conv1d.conv.weight,\nmodel.layers.10.attention.v_conv1d.conv.weight,\nmodel.layers.10.mlp.gate.gate_proj.biases,\nmodel.layers.10.mlp.gate.gate_proj.scales,\nmodel.layers.10.mlp.gate.gate_proj.weight,\nmodel.layers.11.mlp.gate.gate_proj.biases,\nmodel.layers.11.mlp.gate.gate_proj.scales,\nmodel.layers.11.mlp.gate.gate_proj.weight,\nmodel.layers.12.attention.k_conv1d.conv.weight,\nmodel.layers.12.attention.q_conv1d.conv.weight,\nmodel.layers.12.attention.v_conv1d.conv.weight,\nmodel.layers.12.mlp.gate.gate_proj.biases,\nmodel.layers.12.mlp.gate.gate_proj.scales,\nmodel.layers.12.mlp.gate.gate_proj.weight,\nmodel.layers.13.attention.k_conv1d.conv.weight,\nmodel.layers.13.attention.q_conv1d.conv.weight,\nmodel.layers.13.attention.v_conv1d.conv.weight,\nmodel.layers.13.mlp.gate.gate_proj.biases,\nmodel.layers.13.mlp.gate.gate_proj.scales,\nmodel.layers.13.mlp.gate.gate_proj.weight,\nmodel.layers.14.attention.k_conv1d.conv.weight,\nmodel.layers.14.attention.q_conv1d.conv.weight,\nmodel.layers.14.attention.v_conv1d.conv.weight,\nmodel.layers.14.mlp.gate.gate_proj.biases,\nmodel.layers.14.mlp.gate.gate_proj.scales,\nmodel.layers.14.mlp.gate.gate_proj.weight,\nmodel.layers.15.attention.k_conv1d.conv.weight,\nmodel.layers.15.attention.q_conv1d.conv.weight,\nmodel.layers.15.attention.v_conv1d.conv.weight,\nmodel.layers.15.mlp.gate.gate_proj.biases,\nmodel.layers.15.mlp.gate.gate_proj.scales,\nmodel.layers.15.mlp.gate.gate_proj.weight,\nmodel.layers.16.attention.k_conv1d.conv.weight,\nmodel.layers.16.attention.q_conv1d.conv.weight,\nmodel.layers.16.attention.v_conv1d.conv.weight,\nmodel.layers.16.mlp.gate.gate_proj.biases,\nmodel.layers.16.mlp.gate.gate_proj.scales,\nmodel.layers.16.mlp.gate.gate_proj.weight,\nmodel.layers.17.mlp.gate.gate_proj.biases,\nmodel.layers.17.mlp.gate.gate_proj.scales,\nmodel.layers.17.mlp.gate.gate_proj.weight,\nmodel.layers.18.attention.k_conv1d.conv.weight,\nmodel.layers.18.attention.q_conv1d.conv.weight,\nmodel.layers.18.attention.v_conv1d.conv.weight,\nmodel.layers.18.mlp.gate.gate_proj.biases,\nmodel.layers.18.mlp.gate.gate_proj.scales,\nmodel.layers.18.mlp.gate.gate_proj.weight,\nmodel.layers.19.attention.k_conv1d.conv.weight,\nmodel.layers.19.attention.q_conv1d.conv.weight,\nmodel.layers.19.attention.v_conv1d.conv.weight,\nmodel.layers.19.mlp.gate.gate_proj.biases,\nmodel.layers.19.mlp.gate.gate_proj.scales,\nmodel.layers.19.mlp.gate.gate_proj.weight,\nmodel.layers.2.attention.k_conv1d.conv.weight,\nmodel.layers.2.attention.q_conv1d.conv.weight,\nmodel.layers.2.attention.v_conv1d.conv.weight,\nmodel.layers.2.mlp.gate.gate_proj.biases,\nmodel.layers.2.mlp.gate.gate_proj.scales,\nmodel.layers.2.mlp.gate.gate_proj.weight,\nmodel.layers.20.attention.k_conv1d.conv.weight,\nmodel.layers.20.attention.q_conv1d.conv.weight,\nmodel.layers.20.attention.v_conv1d.conv.weight,\nmodel.layers.20.mlp.gate.gate_proj.biases,\nmodel.layers.20.mlp.gate.gate_proj.scales,\nmodel.layers.20.mlp.gate.gate_proj.weight,\nmodel.layers.21.attention.k_conv1d.conv.weight,\nmodel.layers.21.attention.q_conv1d.conv.weight,\nmodel.layers.21.attention.v_conv1d.conv.weight,\nmodel.layers.21.mlp.gate.gate_proj.biases,\nmodel.layers.21.mlp.gate.gate_proj.scales,\nmodel.layers.21.mlp.gate.gate_proj.weight,\nmodel.layers.22.attention.k_conv1d.conv.weight,\nmodel.layers.22.attention.q_conv1d.conv.weight,\nmodel.layers.22.attention.v_conv1d.conv.weight,\nmodel.layers.22.mlp.gate.gate_proj.biases,\nmodel.layers.22.mlp.gate.gate_proj.scales,\nmodel.layers.22.mlp.gate.gate_proj.weight,\nmodel.layers.23.mlp.gate.gate_proj.biases,\nmodel.layers.23.mlp.gate.gate_proj.scales,\nmodel.layers.23.mlp.gate.gate_proj.weight,\nmodel.layers.24.attention.k_conv1d.conv.weight,\nmodel.layers.24.attention.q_conv1d.conv.weight,\nmodel.layers.24.attention.v_conv1d.conv.weight,\nmodel.layers.24.mlp.gate.gate_proj.biases,\nmodel.layers.24.mlp.gate.gate_proj.scales,\nmodel.layers.24.mlp.gate.gate_proj.weight,\nmodel.layers.25.attention.k_conv1d.conv.weight,\nmodel.layers.25.attention.q_conv1d.conv.weight,\nmodel.layers.25.attention.v_conv1d.conv.weight,\nmodel.layers.25.mlp.gate.gate_proj.biases,\nmodel.layers.25.mlp.gate.gate_proj.scales,\nmodel.layers.25.mlp.gate.gate_proj.weight,\nmodel.layers.26.attention.k_conv1d.conv.weight,\nmodel.layers.26.attention.q_conv1d.conv.weight,\nmodel.layers.26.attention.v_conv1d.conv.weight,\nmodel.layers.26.mlp.gate.gate_proj.biases,\nmodel.layers.26.mlp.gate.gate_proj.scales,\nmodel.layers.26.mlp.gate.gate_proj.weight,\nmodel.layers.27.attention.k_conv1d.conv.weight,\nmodel.layers.27.attention.q_conv1d.conv.weight,\nmodel.layers.27.attention.v_conv1d.conv.weight,\nmodel.layers.27.mlp.gate.gate_proj.biases,\nmodel.layers.27.mlp.gate.gate_proj.scales,\nmodel.layers.27.mlp.gate.gate_proj.weight,\nmodel.layers.28.attention.k_conv1d.conv.weight,\nmodel.layers.28.attention.q_conv1d.conv.weight,\nmodel.layers.28.attention.v_conv1d.conv.weight,\nmodel.layers.28.mlp.gate.gate_proj.biases,\nmodel.layers.28.mlp.gate.gate_proj.scales,\nmodel.layers.28.mlp.gate.gate_proj.weight,\nmodel.layers.29.mlp.gate.gate_proj.biases,\nmodel.layers.29.mlp.gate.gate_proj.scales,\nmodel.layers.29.mlp.gate.gate_proj.weight,\nmodel.layers.3.attention.k_conv1d.conv.weight,\nmodel.layers.3.attention.q_conv1d.conv.weight,\nmodel.layers.3.attention.v_conv1d.conv.weight,\nmodel.layers.3.mlp.gate.gate_proj.biases,\nmodel.layers.3.mlp.gate.gate_proj.scales,\nmodel.layers.3.mlp.gate.gate_proj.weight,\nmodel.layers.30.attention.k_conv1d.conv.weight,\nmodel.layers.30.attention.q_conv1d.conv.weight,\nmodel.layers.30.attention.v_conv1d.conv.weight,\nmodel.layers.30.mlp.gate.gate_proj.biases,\nmodel.layers.30.mlp.gate.gate_proj.scales,\nmodel.layers.30.mlp.gate.gate_proj.weight,\nmodel.layers.31.attention.k_conv1d.conv.weight,\nmodel.layers.31.attention.q_conv1d.conv.weight,\nmodel.layers.31.attention.v_conv1d.conv.weight,\nmodel.layers.31.mlp.gate.gate_proj.biases,\nmodel.layers.31.mlp.gate.gate_proj.scales,\nmodel.layers.31.mlp.gate.gate_proj.weight,\nmodel.layers.32.attention.k_conv1d.conv.weight,\nmodel.layers.32.attention.q_conv1d.conv.weight,\nmodel.layers.32.attention.v_conv1d.conv.weight,\nmodel.layers.32.mlp.gate.gate_proj.biases,\nmodel.layers.32.mlp.gate.gate_proj.scales,\nmodel.layers.32.mlp.gate.gate_proj.weight,\nmodel.layers.33.attention.k_conv1d.conv.weight,\nmodel.layers.33.attention.q_conv1d.conv.weight,\nmodel.layers.33.attention.v_conv1d.conv.weight,\nmodel.layers.33.mlp.gate.gate_proj.biases,\nmodel.layers.33.mlp.gate.gate_proj.scales,\nmodel.layers.33.mlp.gate.gate_proj.weight,\nmodel.layers.34.attention.k_conv1d.conv.weight,\nmodel.layers.34.attention.q_conv1d.conv.weight,\nmodel.layers.34.attention.v_conv1d.conv.weight,\nmodel.layers.34.mlp.gate.gate_proj.biases,\nmodel.layers.34.mlp.gate.gate_proj.scales,\nmodel.layers.34.mlp.gate.gate_proj.weight,\nmodel.layers.35.mlp.gate.gate_proj.biases,\nmodel.layers.35.mlp.gate.gate_proj.scales,\nmodel.layers.35.mlp.gate.gate_proj.weight,\nmodel.layers.36.attention.k_conv1d.conv.weight,\nmodel.layers.36.attention.q_conv1d.conv.weight,\nmodel.layers.36.attention.v_conv1d.conv.weight,\nmodel.layers.36.mlp.gate.gate_proj.biases,\nmodel.layers.36.mlp.gate.gate_proj.scales,\nmodel.layers.36.mlp.gate.gate_proj.weight,\nmodel.layers.37.attention.k_conv1d.conv.weight,\nmodel.layers.37.attention.q_conv1d.conv.weight,\nmodel.layers.37.attention.v_conv1d.conv.weight,\nmodel.layers.37.mlp.gate.gate_proj.biases,\nmodel.layers.37.mlp.gate.gate_proj.scales,\nmodel.layers.37.mlp.gate.gate_proj.weight,\nmodel.layers.38.attention.k_conv1d.conv.weight,\nmodel.layers.38.attention.q_conv1d.conv.weight,\nmodel.layers.38.attention.v_conv1d.conv.weight,\nmodel.layers.38.mlp.gate.gate_proj.biases,\nmodel.layers.38.mlp.gate.gate_proj.scales,\nmodel.layers.38.mlp.gate.gate_proj.weight,\nmodel.layers.39.attention.k_conv1d.conv.weight,\nmodel.layers.39.attention.q_conv1d.conv.weight,\nmodel.layers.39.attention.v_conv1d.conv.weight,\nmodel.layers.39.mlp.gate.gate_proj.biases,\nmodel.layers.39.mlp.gate.gate_proj.scales,\nmodel.layers.39.mlp.gate.gate_proj.weight,\nmodel.layers.4.attention.k_conv1d.conv.weight,\nmodel.layers.4.attention.q_conv1d.conv.weight,\nmodel.layers.4.attention.v_conv1d.conv.weight,\nmodel.layers.4.mlp.gate.gate_proj.biases,\nmodel.layers.4.mlp.gate.gate_proj.scales,\nmodel.layers.4.mlp.gate.gate_proj.weight,\nmodel.layers.40.attention.k_conv1d.conv.weight,\nmodel.layers.40.attention.q_conv1d.conv.weight,\nmodel.layers.40.attention.v_conv1d.conv.weight,\nmodel.layers.40.mlp.gate.gate_proj.biases,\nmodel.layers.40.mlp.gate.gate_proj.scales,\nmodel.layers.40.mlp.gate.gate_proj.weight,\nmodel.layers.41.mlp.gate.gate_proj.biases,\nmodel.layers.41.mlp.gate.gate_proj.scales,\nmodel.layers.41.mlp.gate.gate_proj.weight,\nmodel.layers.5.mlp.gate.gate_proj.biases,\nmodel.layers.5.mlp.gate.gate_proj.scales,\nmodel.layers.5.mlp.gate.gate_proj.weight,\nmodel.layers.6.attention.k_conv1d.conv.weight,\nmodel.layers.6.attention.q_conv1d.conv.weight,\nmodel.layers.6.attention.v_conv1d.conv.weight,\nmodel.layers.6.mlp.gate.gate_proj.biases,\nmodel.layers.6.mlp.gate.gate_proj.scales,\nmodel.layers.6.mlp.gate.gate_proj.weight,\nmodel.layers.7.attention.k_conv1d.conv.weight,\nmodel.layers.7.attention.q_conv1d.conv.weight,\nmodel.layers.7.attention.v_conv1d.conv.weight,\nmodel.layers.7.mlp.gate.gate_proj.biases,\nmodel.layers.7.mlp.gate.gate_proj.scales,\nmodel.layers.7.mlp.gate.gate_proj.weight,\nmodel.layers.8.attention.k_conv1d.conv.weight,\nmodel.layers.8.attention.q_conv1d.conv.weight,\nmodel.layers.8.attention.v_conv1d.conv.weight,\nmodel.layers.8.mlp.gate.gate_proj.biases,\nmodel.layers.8.mlp.gate.gate_proj.scales,\nmodel.layers.8.mlp.gate.gate_proj.weight,\nmodel.layers.9.attention.k_conv1d.conv.weight,\nmodel.layers.9.attention.q_conv1d.conv.weight,\nmodel.layers.9.attention.v_conv1d.conv.weight,\nmodel.layers.9.mlp.gate.gate_proj.biases,\nmodel.layers.9.mlp.gate.gate_proj.scales,\nmodel.layers.9.mlp.gate.gate_proj.weight.') Source, metric, and revieweight_models_bench/results/run_20261002_150547/ling124_2048_1234_mlx-lm_serial_3Output token slope after token 32 |
| North-Mini-Code-1.0 4-bitserialmlx-lm + mlx-vlm model 0.32.1.dev4+g53b9af378 | 2,048 / 1,024 | 88.49 | 0.93 | 1,380.0 | 7/8 | Diagnostic The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_150547/north30_2048_1234_mlx-lm_serial_0Output token slope after token 32 |
| North-Mini-Code-1.0 4-bitserialmlx-lm + mlx-vlm model 0.32.1.dev4+g53b9af378 | — / —Requested input: 260,864 | — | — | — | — | Incomplete KeyboardInterrupt('signal 15') Source, metric, and revieweight_models_bench/results/run_20261002_150547/north30_260864_1234_mlx-lm_serial_2Output token slope after token 32 |
| North-Mini-Code-1.0 4-bitserialmlx-lm + mlx-vlm model 0.32.1.dev4+g53b9af378 | 32,768 / 1,024 | 78.14 | 20.31 | 1,380.0 | 8/8 | Pass Source, metric, and revieweight_models_bench/results/run_20261002_150547/north30_32768_1234_mlx-lm_serial_1Output token slope after token 32 |
| Ling-3.0-flash 4-bitserialmlx-lm + local Ling adapter 0.32.1.dev4+g53b9af378 | 2,048 / 1,024 | 64.46 | 1.89 | 1,380.0 | 8/8 | Pass Source, metric, and revieweight_models_bench/results/run_20261002_153149/ling124_2048_1234_mlx-lm_serial_0Output token slope after token 32 |
| Ling-3.0-flash 4-bitserialmlx-lm + local Ling adapter 0.32.1.dev4+g53b9af378 | — / —Requested input: 260,864 | — | — | — | — | Incomplete KeyboardInterrupt('signal 15') Source, metric, and revieweight_models_bench/results/run_20261002_153149/ling124_260864_1234_mlx-lm_serial_2Output token slope after token 32 |
| Ling-3.0-flash 4-bitserialmlx-lm + local Ling adapter 0.32.1.dev4+g53b9af378 | 32,768 / 929 | 59.01 | 25.15 | 1,380.0 | 8/8 | Diagnostic Source, metric, and revieweight_models_bench/results/run_20261002_153149/ling124_32768_1234_mlx-lm_serial_1Output token slope after token 32 |
| MiMo-V2.6-Distill-Qwen-9B mixed 4/6-bitserial_diagnostic_loadmlx-lm 0.32.1.dev4+g53b9af378 | — / —Requested input: 260,864 | — | — | — | — | Incomplete KeyboardInterrupt('signal 15') Source, metric, and revieweight_models_bench/results/run_20261002_153149/mimo9_260864_1234_mlx-lm_serial_3Output token slope after token 32 |
| KAT-Coder-V2.5-Dev OptiQ 4-bitserial_prefill_pause2000msmlx-lm 0.32.1.dev4+g53b9af378 | 260,864 / 1,024 | 13.27 | 1,084.43 | 338.0 | 8/8 | Diagnostic normal_decode_clock; decode_clamp; load Source, metric, and revieweight_models_bench/results/run_20261002_160205/kat35_260864_1234_mlx-lm_serial_10Output token slope after token 32 |
| MiMo-V2.6-Distill-Qwen-9B mixed 4/6-bitserial_prefill_pause2000msmlx-lm 0.32.1.dev4+g53b9af378 | 2,048 / 1,024 | 98.86 | 5.42 | 1,380.0 | 8/8 | Pass Source, metric, and revieweight_models_bench/results/run_20261002_160205/mimo9_2048_1234_mlx-lm_serial_0Output token slope after token 32 |
| MiMo-V2.6-Distill-Qwen-9B mixed 4/6-bitserial_prefill_pause2000msmlx-lm 0.32.1.dev4+g53b9af378 | 260,864 / 1,024 | 15.81 | 1,448.87 | 338.0 | 8/8 | Diagnostic normal_decode_clock; decode_clamp; load The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_160205/mimo9_260864_1234_mlx-lm_serial_9Output token slope after token 32 |
| Qwen3.5-2B 4-bitserial_kv8_after_prefillmlx-lm 0.32.1.dev4+g53b9af378 | 2,048 / 1,024 | 265.86 | 0.34 | 1,380.0 | 8/8 | Pass Source, metric, and revieweight_models_bench/results/run_20261002_160205/qwen2_2048_1234_mlx-lm_serial_1Output token slope after token 32 |
| Qwen3.5-2B 4-bitserial_qwen_recommendedmlx-lm 0.32.1.dev4+g53b9af378 | 2,048 / 1,024 | 253.57 | 0.31 | 1,380.0 | 0/8 | Diagnostic The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_160205/qwen2_2048_1234_mlx-lm_serial_6Output token slope after token 32 |
| Qwen3.5-2B 4-bitserial_kv8_after_prefillmlx-lm 0.32.1.dev4+g53b9af378 | 260,864 / 1,024 | 87.77 | 134.68 | 1,380.0 | 8/8 | Pass Source, metric, and revieweight_models_bench/results/run_20261002_160205/qwen2_260864_1234_mlx-lm_serial_3Output token slope after token 32 |
| Qwen3.5-2B 4-bitserial_qwen_recommendedmlx-lm 0.32.1.dev4+g53b9af378 | 260,864 / 1,024 | 80.37 | 134.56 | 1,380.0 | 0/8 | Diagnostic The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_160205/qwen2_260864_1234_mlx-lm_serial_8Output token slope after token 32 |
| Qwen3.5-2B 4-bitserial_kv8_after_prefillmlx-lm 0.32.1.dev4+g53b9af378 | 260,864 / 1,024 | 87.14 | 135.07 | 1,373.0 | 0/8 | Diagnostic The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_160205/qwen2_260864_1235_mlx-lm_serial_4Output token slope after token 32 |
| Qwen3.5-2B 4-bitserial_kv8_after_prefillmlx-lm 0.32.1.dev4+g53b9af378 | 260,864 / 1,024 | 87.62 | 134.56 | 1,380.0 | 8/8 | Pass Source, metric, and revieweight_models_bench/results/run_20261002_160205/qwen2_260864_1236_mlx-lm_serial_5Output token slope after token 32 |
| Qwen3.5-2B 4-bitserial_kv8_after_prefillmlx-lm 0.32.1.dev4+g53b9af378 | 32,768 / 1,024 | 215.89 | 5.77 | 1,380.0 | 0/8 | Diagnostic The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_160205/qwen2_32768_1234_mlx-lm_serial_2Output token slope after token 32 |
| Qwen3.5-2B 4-bitserial_qwen_recommendedmlx-lm 0.32.1.dev4+g53b9af378 | 32,768 / 1,024 | 200.95 | 5.77 | 1,380.0 | 0/8 | Diagnostic The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_160205/qwen2_32768_1234_mlx-lm_serial_7Output token slope after token 32 |
| Gemma 4 26B-A4B QAT 4-bitgemma-vlm_mtpmlx-vlm 0.7.4 | 2,048 / 1,024 | 117.60 | 0.81 | 1,380.0 | 8/8 | Diagnostic matched_serial_exactness; valid_harness Source, metric, and revieweight_models_bench/results/run_20261002_173233/gemma26_2048_1234_gemma-vlm_mtp_8Output token slope after token 32 |
| Gemma 4 26B-A4B QAT 4-bitgemma-vlm_serialmlx-vlm 0.7.4 | 2,048 / 1,024 | 99.14 | 0.82 | 1,380.0 | 8/8 | Diagnostic valid_harness Source, metric, and revieweight_models_bench/results/run_20261002_173233/gemma26_2048_1234_gemma-vlm_serial_7Output token slope after token 32 |
| Ling-3.0-flash 4-bitserial_prefill_pause2000msmlx-lm + local Ling adapter 0.32.1.dev4+g53b9af378 | 260,864 / 1,024 | 22.09 | 1,492.34 | 649.0 | 8/8 | Diagnostic normal_decode_clock Source, metric, and revieweight_models_bench/results/run_20261002_173233/ling124_260864_1234_mlx-lm_serial_6Output token slope after token 32 |
| North-Mini-Code-1.0 4-bitserial_prefill_pause2000msmlx-lm + mlx-vlm model 0.32.1.dev4+g53b9af378 | 260,864 / 75 | 42.50 | 1,056.11 | 1,378.0 | 4/8 | Diagnostic decode_samples The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_173233/north30_260864_1234_mlx-lm_serial_5Output token slope after token 32 |
| Qwen3.5-2B 4-bitserial_kv4_after_prefillmlx-lm 0.32.1.dev4+g53b9af378 | 2,048 / 1,024 | 263.97 | 0.33 | 1,380.0 | 8/8 | Pass Source, metric, and revieweight_models_bench/results/run_20261002_173233/qwen2_2048_1234_mlx-lm_serial_0Output token slope after token 32 |
| Qwen3.5-2B 4-bitserial_kv4_after_prefillmlx-lm 0.32.1.dev4+g53b9af378 | 260,864 / 1,024 | 97.74 | 136.47 | 1,380.0 | 8/8 | Pass Source, metric, and revieweight_models_bench/results/run_20261002_173233/qwen2_260864_1234_mlx-lm_serial_2Output token slope after token 32 |
| Qwen3.5-2B 4-bitserial_kv4_after_prefillmlx-lm 0.32.1.dev4+g53b9af378 | 260,864 / 1,024 | 97.80 | 137.03 | 1,380.0 | 0/8 | Diagnostic The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_173233/qwen2_260864_1235_mlx-lm_serial_3Output token slope after token 32 |
| Qwen3.5-2B 4-bitserial_kv4_after_prefillmlx-lm 0.32.1.dev4+g53b9af378 | 260,864 / 1,024 | 97.86 | 136.43 | 1,380.0 | 0/8 | Diagnostic The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_173233/qwen2_260864_1236_mlx-lm_serial_4Output token slope after token 32 |
| Qwen3.5-2B 4-bitserial_kv4_after_prefillmlx-lm 0.32.1.dev4+g53b9af378 | 32,768 / 1,024 | 222.04 | 5.77 | 1,380.0 | 0/8 | Diagnostic The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_173233/qwen2_32768_1234_mlx-lm_serial_1Output token slope after token 32 |
| Gemma 4 26B-A4B QAT 4-bitgemma-vlm_mtpmlx-vlm 0.7.4 | — / —Requested input: 2,048 | — | — | — | — | Incomplete RuntimeError('Fresh GEMM failed: 17.609271709172713') Source, metric, and revieweight_models_bench/results/run_20261002_191124/gemma26_2048_1234_gemma-vlm_mtp_1Output token slope after token 32 |
| Gemma 4 26B-A4B QAT 4-bitgemma-vlm_serialmlx-vlm 0.7.4 | 2,048 / 1,024 | 97.02 | 0.82 | 1,380.0 | 8/8 | Pass Source, metric, and revieweight_models_bench/results/run_20261002_191124/gemma26_2048_1234_gemma-vlm_serial_0Output token slope after token 32 |
| Gemma 4 26B-A4B QAT 4-bitgemma-vlm_mtpmlx-vlm 0.7.4 | 2,048 / 1,024 | 116.41 | 0.81 | 1,380.0 | 8/8 | Diagnostic matched_serial_exactness Source, metric, and revieweight_models_bench/results/run_20261002_191509/gemma26_2048_1234_gemma-vlm_mtp_1Output token slope after token 32 |
| Gemma 4 26B-A4B QAT 4-bitgemma-vlm_serialmlx-vlm 0.7.4 | 2,048 / 1,024 | 96.68 | 0.82 | 1,380.0 | 8/8 | Pass Source, metric, and revieweight_models_bench/results/run_20261002_191509/gemma26_2048_1234_gemma-vlm_serial_0Output token slope after token 32 |
| MiMo 9B MTPLX 6-bit targetmtplx_mtpMTPLX 2.12.0 | 2,048 / 1,024 | 117.05 | 1.54 | 1,379.0 | 8/8 | Diagnostic matched_serial_exactness Source, metric, and revieweight_models_bench/results/run_20261002_191509/mimo9_mtplx_2048_1234_mtplx_mtp_3Output token slope after token 32 |
| MiMo 9B MTPLX 6-bit targetmtplx_serialMTPLX 2.12.0 | 2,048 / 1,024 | 70.30 | 1.46 | 1,380.0 | 8/8 | Diagnostic no_external_probe Source, metric, and revieweight_models_bench/results/run_20261002_191509/mimo9_mtplx_2048_1234_mtplx_serial_2Output token slope after token 32 |
| Qwen3.5-2B 4-bitserial_kv4_g128_after_prefillmlx-lm 0.32.1.dev4+g53b9af378 | 2,048 / 1,024 | 262.90 | 0.33 | 1,380.0 | 8/8 | Pass Source, metric, and revieweight_models_bench/results/run_20261002_191509/qwen2_2048_1234_mlx-lm_serial_4Output token slope after token 32 |
| Qwen3.5-2B 4-bitserial_kv4_g128_after_prefillmlx-lm 0.32.1.dev4+g53b9af378 | 260,864 / 1,024 | 98.31 | 136.60 | 1,380.0 | 0/8 | Diagnostic The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_191509/qwen2_260864_1234_mlx-lm_serial_6Output token slope after token 32 |
| Qwen3.5-2B 4-bitserial_kv4_g128_after_prefillmlx-lm 0.32.1.dev4+g53b9af378 | 260,864 / 1,024 | 98.48 | 135.47 | 1,380.0 | 0/8 | Diagnostic The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_191509/qwen2_260864_1235_mlx-lm_serial_7Output token slope after token 32 |
| Qwen3.5-2B 4-bitserial_kv4_g128_after_prefillmlx-lm 0.32.1.dev4+g53b9af378 | 260,864 / 1,024 | 98.80 | 134.34 | 1,380.0 | 0/8 | Diagnostic The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_191509/qwen2_260864_1236_mlx-lm_serial_8Output token slope after token 32 |
| Qwen3.5-2B 4-bitserial_kv4_g128_after_prefillmlx-lm 0.32.1.dev4+g53b9af378 | 32,768 / 1,024 | 217.09 | 5.86 | 1,380.0 | 0/8 | Diagnostic The automatic quality check failed. Source, metric, and revieweight_models_bench/results/run_20261002_191509/qwen2_32768_1234_mlx-lm_serial_5Output token slope after token 32 |
Final Qwen3.8 MTPLX and TensorFold variants33 records
All thirty-three attempts from the final combined report. Three dense full-context variants remain untested.
| Model / mode | Input / output | Decode t/s | First token, s | GPU MHz | Recall | Result / limits |
|---|---|---|---|---|---|---|
| Qwen3.8-27B Bare Speedmtplx_mtpMTPLX 2.12.2 | 2,048 / 1,024 | 61.99 | 4.69 | 1,377.0 | 8/8 | Diagnostic matched_serial_exactness Source, metric, and reviewqwen38_variants_bench/results/run_20261004_185731/27b_bare_2048_1234_mtplx_mtp_1Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses the archive task.The output ends at the 1024-token limit.This review does not validate each claim in the later text. |
| Qwen3.8-27B Bare Speedmtplx_serialMTPLX 2.12.2 | 2,048 / 1,024 | 32.41 | 4.61 | 1,380.0 | 8/8 | Pass Source, metric, and reviewqwen38_variants_bench/results/run_20261004_185731/27b_bare_2048_1234_mtplx_serial_0Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses the archive task.The output ends at the 1024-token limit.This review does not validate each claim in the later text. |
| Qwen3.8-27B Bare Speedmtplx_mtpMTPLX 2.12.2 | 32,768 / 1,024 | 50.93 | 84.77 | 1,377.5 | 8/8 | Diagnostic matched_serial_exactness Source, metric, and reviewqwen38_variants_bench/results/run_20261004_185731/27b_bare_32768_1234_mtplx_mtp_3Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses the archive task.The output ends at the 1024-token limit.This review does not validate each claim in the later text. |
| Qwen3.8-27B Bare Speedmtplx_serialMTPLX 2.12.2 | 32,768 / 1,024 | 28.07 | 82.73 | 1,380.0 | 8/8 | Pass Source, metric, and reviewqwen38_variants_bench/results/run_20261004_185731/27b_bare_32768_1234_mtplx_serial_2Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses the archive task.The output ends at the 1024-token limit.This review does not validate each claim in the later text. |
| Qwen3.8-27B Bare Speedmtplx_serialMTPLX 2.12.2 | — / —Requested input: 260,864 | — | — | — | — | Incomplete Prefill exceeded 3600 seconds Prefill exceeded 3600 seconds Source, metric, and reviewqwen38_variants_bench/results/run_20261004_185731/27b_bare_260864_1234_mtplx_serial_4Output token slope after token 32 |
| Qwen3.8-27B Optimized Speedmtplx_mtpMTPLX 2.12.2 | 2,048 / 1,024 | 55.47 | 4.76 | 1,377.5 | 8/8 | Diagnostic matched_serial_exactness Source, metric, and reviewqwen38_variants_bench/results/run_20261004_202905/27b_speed_2048_1234_mtplx_mtp_1Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses the archive task.The output ends at the 1024-token limit.This review does not validate each claim in the later text. |
| Qwen3.8-27B Optimized Speedmtplx_serialMTPLX 2.12.2 | 2,048 / 1,024 | 27.44 | 4.67 | 1,380.0 | 8/8 | Pass Source, metric, and reviewqwen38_variants_bench/results/run_20261004_202905/27b_speed_2048_1234_mtplx_serial_0Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses the archive task.The output ends at the 1024-token limit.This review does not validate each claim in the later text. |
| Qwen3.8-27B Optimized Speedmtplx_mtpMTPLX 2.12.2 | 32,768 / 1,024 | 43.42 | 85.46 | 1,378.0 | 8/8 | Diagnostic matched_serial_exactness Source, metric, and reviewqwen38_variants_bench/results/run_20261004_202905/27b_speed_32768_1234_mtplx_mtp_3Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses the archive task.The output ends at the 1024-token limit.This review does not validate each claim in the later text. |
| Qwen3.8-27B Optimized Speedmtplx_serialMTPLX 2.12.2 | 32,768 / 1,024 | 24.17 | 83.41 | 1,380.0 | 8/8 | Pass Source, metric, and reviewqwen38_variants_bench/results/run_20261004_202905/27b_speed_32768_1234_mtplx_serial_2Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses the archive task.The spelling example repeats the same name without a visible difference.The output ends at the 1024-token limit.This review does not validate each claim in the later text. |
| Qwen3.8-Flash-Next Bare Speedmtplx_mtpMTPLX 2.12.2 | 2,048 / 1,024 | 65.10 | 1.76 | 1,380.0 | 8/8 | Diagnostic matched_serial_exactness Source, metric, and reviewqwen38_variants_bench/results/run_20261004_211626/flash_bare_2048_1234_mtplx_mtp_1Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses the archive task.The output ends at the 1024-token limit.This review does not validate each claim in the later text. |
| Qwen3.8-Flash-Next Bare Speedmtplx_serialMTPLX 2.12.2 | 2,048 / 1,024 | 40.73 | 1.88 | 1,373.0 | 8/8 | Pass Source, metric, and reviewqwen38_variants_bench/results/run_20261004_211626/flash_bare_2048_1234_mtplx_serial_0Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses the archive task.The output ends at the 1024-token limit.This review does not validate each claim in the later text. |
| Qwen3.8-Flash-Next Bare Speedmtplx_mtpMTPLX 2.12.2 | 32,768 / 1,024 | 54.59 | 36.24 | 1,380.0 | 8/8 | Diagnostic matched_serial_exactness Source, metric, and reviewqwen38_variants_bench/results/run_20261004_211626/flash_bare_32768_1234_mtplx_mtp_3Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses the archive task.Some later claims about the archive lack evidence.The output ends at the 1024-token limit. |
| Qwen3.8-Flash-Next Bare Speedmtplx_serialMTPLX 2.12.2 | 32,768 / 1,024 | 38.06 | 34.85 | 1,373.0 | 8/8 | Pass Source, metric, and reviewqwen38_variants_bench/results/run_20261004_211626/flash_bare_32768_1234_mtplx_serial_2Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses the archive task.The output ends at the 1024-token limit.This review does not validate each claim in the later text. |
| Qwen3.8-Flash-Next Bare Speedmtplx_mtpMTPLX 2.12.2 | — / —Requested input: 260,864 | — | — | — | — | Incomplete KeyboardInterrupt('signal 15') System load exceeded16 twice Source, metric, and reviewqwen38_variants_bench/results/run_20261005_002720/flash_bare_260864_1234_mtplx_mtp_1Output token slope after token 32 |
| Qwen3.8-Flash-Next Bare Speedmtplx_serialMTPLX 2.12.2 | — / —Requested input: 260,864 | — | — | — | — | Incomplete KeyboardInterrupt('signal 15') System load exceeded the qualification limit; the TensorFold control takes priority Source, metric, and reviewqwen38_variants_bench/results/run_20261004_211626/flash_bare_260864_1234_mtplx_serial_4Output token slope after token 32 |
| Qwen3.8-Flash-Next Bare Speedmtplx_serialMTPLX 2.12.2 | — / —Requested input: 260,864 | — | — | — | — | Incomplete RuntimeError('[METAL] Command buffer execution failed: Caused GPU Timeout Error (00000002:kIOGPUCommandBufferCallbackErrorTimeout).') Source, metric, and reviewqwen38_variants_bench/results/run_20261005_001052/flash_bare_260864_1234_mtplx_serial_4Output token slope after token 32 |
| Qwen3.8-Flash-Next Bare Speedmtplx_serialMTPLX 2.12.2 | 260,864 / 1,024 | 23.35 | 2,322.45 | 885.0 | 8/8 | Diagnostic normal_decode_clock Source, metric, and reviewqwen38_variants_bench/results/run_20261005_002720/flash_bare_260864_1234_mtplx_serial_0Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses archive verification and conflict checks.The output ends at the 1024-token limit.This review does not validate every claim or quotation in the later text. |
| Qwen3.8-Flash-Next Optimized Speedmtplx_mtpMTPLX 2.12.2 | 2,048 / 1,024 | 64.51 | 1.79 | 1,380.0 | 8/8 | Diagnostic matched_serial_exactness Source, metric, and reviewqwen38_variants_bench/results/run_20261005_001052/flash_speed_2048_1234_mtplx_mtp_1Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses the archive task.The cited Reykjavik context matches the archive.The output ends at the 1024-token limit.This review does not validate every claim in the later text. |
| Qwen3.8-Flash-Next Optimized Speedmtplx_serialMTPLX 2.12.2 | 2,048 / 1,024 | 37.88 | 1.78 | 1,373.0 | 8/8 | Pass Source, metric, and reviewqwen38_variants_bench/results/run_20261005_001052/flash_speed_2048_1234_mtplx_serial_0Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses the archive task.The archive body has the partial final phrase that the answer describes.The output ends at the 1024-token limit.This review does not validate every claim in the later text. |
| Qwen3.8-Flash-Next Optimized Speedmtplx_mtpMTPLX 2.12.2 | 32,768 / 1,024 | 67.10 | 37.29 | 1,380.0 | 8/8 | Diagnostic matched_serial_exactness Source, metric, and reviewqwen38_variants_bench/results/run_20261005_001052/flash_speed_32768_1234_mtplx_mtp_3Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses the archive task.The guide repeats the eight records once as extraction results.The output ends at the 1024-token limit.This review does not validate every claim in the later text. |
| Qwen3.8-Flash-Next Optimized Speedmtplx_serialMTPLX 2.12.2 | 32,768 / 1,024 | 35.79 | 35.64 | 1,373.0 | 8/8 | Pass Source, metric, and reviewqwen38_variants_bench/results/run_20261005_001052/flash_speed_32768_1234_mtplx_serial_2Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses the archive task.The output ends at the 1024-token limit.This review does not validate every claim in the later text. |
| Qwen3.8-Flash-Next Optimized Speedmtplx_mtpMTPLX 2.12.2 | 260,864 / 1,024 | 33.60 | 2,524.62 | 539.0 | 8/8 | Diagnostic normal_decode_clock; load; matched_serial_exactness Source, metric, and reviewqwen38_variants_bench/results/run_20261005_014554/flash_speed_260864_1234_mtplx_mtp_1Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses archive verification and data extraction.The output ends at the 1024-token limit.This review does not validate every claim or quotation in the later text. |
| Qwen3.8-Flash-Next Optimized Speedmtplx_serialMTPLX 2.12.2 | 260,864 / 1,024 | 21.58 | 2,382.92 | 853.5 | 8/8 | Diagnostic normal_decode_clock Source, metric, and reviewqwen38_variants_bench/results/run_20261005_014554/flash_speed_260864_1234_mtplx_serial_0Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses archive verification.The guide says a change in descriptive text indicates a security breach. This test provides no evidence for that claim.The output ends at the 1024-token limit.This review does not validate every claim or quotation in the later text. |
| Qwen3.8-Flash-Next 4-bittensorfold_mtpTensorFold 0.6.5 | 2,048 / 1,024 | 111.89 | 2.53 | 1,380.0 | 8/8 | Pass Source, metric, and reviewqwen38_variants_bench/results/run_20261004_215711/tf_flash_2048_1234_tensorfold_mtp_1Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses the archive task.The output ends at the 1024-token limit.This review does not validate every claim in the later text. |
| Qwen3.8-Flash-Next 4-bittensorfold_serialTensorFold 0.6.5 | 2,048 / 1,024 | 84.78 | 2.50 | 1,380.0 | 8/8 | Pass Source, metric, and reviewqwen38_variants_bench/results/run_20261004_215711/tf_flash_2048_1234_tensorfold_serial_0Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses the archive task.The output ends at the 1024-token limit.This review does not validate every claim in the later text. |
| Qwen3.8-Flash-Next 4-bittensorfold_matrix_mtpTensorFold 0.6.5 | 32,768 / 1,024 | 101.24 | 27.77 | 1,380.0 | 8/8 | Pass Source, metric, and reviewqwen38_variants_bench/results/run_20261004_233659/tf_flash_32768_1234_tensorfold_mtp_1Output token slope after token 32 The output bytes equal the manually reviewed matrix serial output.Every output token matches that serial control.All eight retrieval checks passed.This comparison does not validate every claim in the later text. |
| Qwen3.8-Flash-Next 4-bittensorfold_matrix_serialTensorFold 0.6.5 | 32,768 / 1,024 | 78.05 | 27.82 | 1,380.0 | 8/8 | Pass Source, metric, and reviewqwen38_variants_bench/results/run_20261004_233659/tf_flash_32768_1234_tensorfold_serial_0Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses the archive task.The output ends at the 1024-token limit.This review does not validate every claim in the later text. |
| Qwen3.8-Flash-Next 4-bittensorfold_mtpTensorFold 0.6.5 | 32,768 / 1,024 | 113.70 | 27.83 | 1,380.0 | 8/8 | Pass Source, metric, and reviewqwen38_variants_bench/results/run_20261004_215711/tf_flash_32768_1234_tensorfold_mtp_3Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses the archive task.The output ends at the 1024-token limit.This review does not validate every claim in the later text. |
| Qwen3.8-Flash-Next 4-bittensorfold_serialTensorFold 0.6.5 | 32,768 / 1,024 | 82.18 | 27.78 | 1,380.0 | 8/8 | Pass Source, metric, and reviewqwen38_variants_bench/results/run_20261004_215711/tf_flash_32768_1234_tensorfold_serial_2Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses the archive task.The output ends at the 1024-token limit.This review does not validate every claim in the later text. |
| Qwen3.8-Flash-Next 4-bittensorfold_cooled_prefill_mtpTensorFold 0.6.5 | 260,864 / 1,024 | 93.25 | 735.46 | 1,379.0 | 8/8 | Pass Pause: 489.35 s Source, metric, and reviewqwen38_variants_bench/results/run_20261004_225650/tf_flash_260864_1234_tensorfold_mtp_1Output token slope after token 32 The output bytes equal the manually reviewed serial output.Every output token matches the cold MTP reference and the cooled serial control.All eight retrieval checks passed.This comparison does not validate every claim in the later text. |
| Qwen3.8-Flash-Next 4-bittensorfold_cooled_prefill_serialTensorFold 0.6.5 | 260,864 / 1,024 | 72.06 | 732.93 | 1,380.0 | 8/8 | Pass Pause: 489.78 s Source, metric, and reviewqwen38_variants_bench/results/run_20261004_225650/tf_flash_260864_1234_tensorfold_serial_0Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses the archive task.The output ends at the 1024-token limit.Every output token matches the cold serial reference.This review does not validate every claim in the later text. |
| Qwen3.8-Flash-Next 4-bittensorfold_mtpTensorFold 0.6.5 | 260,864 / 1,024 | 28.92 | 410.50 | 338.0 | 8/8 | Diagnostic normal_decode_clock; decode_clamp Source, metric, and reviewqwen38_variants_bench/results/run_20261004_215711/tf_flash_260864_1234_tensorfold_mtp_5Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses the archive task.The output ends at the 1024-token limit.This review does not validate every claim in the later text. |
| Qwen3.8-Flash-Next 4-bittensorfold_serialTensorFold 0.6.5 | 260,864 / 1,024 | 44.83 | 259.29 | 520.5 | 8/8 | Diagnostic normal_decode_clock Source, metric, and reviewqwen38_variants_bench/results/run_20261004_215711/tf_flash_260864_1234_tensorfold_serial_4Output token slope after token 32 The first eight lines contain the correct city-code pairs.The later text addresses the archive task.The output ends at the 1024-token limit.This review does not validate every claim in the later text. |
Source files and SHA256 hashes162 files
These hashes identify the local source files used for this export. A hash identifies a file; it does not replace its raw contents.
qwen38_variants_bench/all-results.jsonf1031b5d586ad63bcd6b96933a3ac6aba3cec68e742d431a1ec9fcd34882cc12qwen38_variants_bench/results/run_20261004_185731/27b_bare_2048_1234_mtplx_mtp_1/acceleration-comparison.json0aa30b2685c7889f156b20bbc00cc46573101752c29149c420c482687930203dqwen38_variants_bench/results/run_20261004_185731/27b_bare_32768_1234_mtplx_mtp_3/acceleration-comparison.json317de48ffdde1ee0e952326aadd4f28e68405ad55daf206a1f968c85393f16a4qwen38_variants_bench/results/run_20261004_202905/27b_speed_2048_1234_mtplx_mtp_1/acceleration-comparison.jsonb6884a6edae7b4b2445895098fbae608b79d58bc61c78bc9170e725833379641qwen38_variants_bench/results/run_20261004_202905/27b_speed_32768_1234_mtplx_mtp_3/acceleration-comparison.json557a2ec2081d90c0af59d404ea8cda859e6b229c8bd82b17cc9d6015292f17c7qwen38_variants_bench/results/run_20261004_211626/flash_bare_2048_1234_mtplx_mtp_1/acceleration-comparison.jsond4d92474849a336e08fe60732be8930da5217bf54b5069dea48164f49795d73eqwen38_variants_bench/results/run_20261004_211626/flash_bare_32768_1234_mtplx_mtp_3/acceleration-comparison.json7e6602e28c72b80e0421f9f7c2eda6fbf77953a6d48ba4b004ed693bb7dd1e69qwen38_variants_bench/results/run_20261005_001052/flash_speed_2048_1234_mtplx_mtp_1/acceleration-comparison.jsonc2ec3766d7df75fcc36439b542d73ee27f4a15711bd3aab6dba0d1f864515ef0qwen38_variants_bench/results/run_20261005_001052/flash_speed_32768_1234_mtplx_mtp_3/acceleration-comparison.json0b4f965b5a6d978e8c9702b997c497c380509aad3dfbc9a0073e8b2f5f021ec2qwen38_variants_bench/results/run_20261005_014554/flash_speed_260864_1234_mtplx_mtp_1/acceleration-comparison.json8795d9467c9116f4bb47076a62ca6b6100f2dab73cb69d12c878fa6149de1f65qwen38_variants_bench/results/run_20261004_215711/tf_flash_2048_1234_tensorfold_mtp_1/acceleration-comparison.jsone0bcd775b4e53c7b6f465bb455f9f68ac4a5822b84d1eb795c1feb183283d08dqwen38_variants_bench/results/run_20261004_233659/tf_flash_32768_1234_tensorfold_mtp_1/acceleration-comparison.json690e937f8c4459a1877e655c81baabfd94990685a8162e853e15847d6571ff7bqwen38_variants_bench/results/run_20261004_215711/tf_flash_32768_1234_tensorfold_mtp_3/acceleration-comparison.jsona8e57ccef798ce2ada7009296037b2fa42e9dcf9660c9666272e274f6a8d741eqwen38_variants_bench/results/run_20261004_225650/tf_flash_260864_1234_tensorfold_mtp_1/acceleration-comparison.json8f71a02fa82af8c75d2d1c5afd53ad1e15415bd3505210470b04a3621904d1e2qwen38_variants_bench/results/run_20261004_215711/tf_flash_260864_1234_tensorfold_mtp_5/acceleration-comparison.json76be096ebde6cdd84a32a395fc349ce323b7b2b0311cd25316259184309d0e88eight_models_bench/all-results.json02038f190ad95f9451615cf314f117b5031561cccac8834e1a227f3fee8f99e7eight_models_bench/results/run_20261002_173233/gemma26_2048_1234_gemma-vlm_mtp_8/acceleration-comparison.jsonf839b259e240e58f924eb25fd7bca39f61467e9690e8e63ea15d724dd9c60a63eight_models_bench/results/run_20261002_191509/gemma26_2048_1234_gemma-vlm_mtp_1/acceleration-comparison.json78c0db7ba7ca865e67c03e72e2316fe1743c157756c3d8144051bd5cba084d79eight_models_bench/results/run_20261002_191509/mimo9_mtplx_2048_1234_mtplx_mtp_3/acceleration-comparison.jsonf9d5be7d039a850caf2acf6717fb34bb72da1aab0e60e727de60d2f29fb748d7glm53_tensorfold065_bench/all-results.json60a5999b3f108f81b6941771f3c23bf136b3fffdc518e423ece44059c16ee1e8glm53_tensorfold065_bench/results/run_20261005_142827/glm_4bit_2048_1234_tensorfold_serial_0/result.jsona7fa7770b630d274662f195b4dae44883c1ea7fb1175ef66d6385a91d4a20f1eglm53_tensorfold065_bench/results/run_20261005_145619/glm_4bit_2048_1234_tensorfold_mtp_1/acceleration-comparison.json0a172ab62fc1023c1e23ced602b38a1c8b4b90265f378a7b84a3103354ab17e7glm53_tensorfold065_bench/results/run_20261005_145619/glm_4bit_2048_1234_tensorfold_mtp_1/result.json84a54e69155f7447d515751e1337647c9720d9688d7283cd10e9a8e9a8f2725dglm53_tensorfold065_bench/results/run_20261005_145619/glm_4bit_2048_1234_tensorfold_serial_0/result.json5c2783800801e78a4e7a3ebf2f87c845630c83ed0feb427f950d1923fc9ba23aglm53_tensorfold065_bench/results/run_20261005_145619/glm_4bit_260864_1234_tensorfold_mtp_5/acceleration-comparison.json47c20eb7ca78bbf05ae89ae5e7d914d208efdf8b047df61d6908d86415a54205glm53_tensorfold065_bench/results/run_20261005_145619/glm_4bit_260864_1234_tensorfold_mtp_5/result.json81366d70efe698e797cd48b2a632c4df2b7cc891769bb76981b14790af9322adglm53_tensorfold065_bench/results/run_20261005_145619/glm_4bit_260864_1234_tensorfold_mtp_7/acceleration-comparison.json0a0671235a963221e58c57e853dd39c80701df15720d7f1aec65666bbbb4be35glm53_tensorfold065_bench/results/run_20261005_145619/glm_4bit_260864_1234_tensorfold_mtp_7/result.jsonfcb483f8c655a0b37a47b8384c0c4bac847767ef9d6c8cec2dbeba828846ace7glm53_tensorfold065_bench/results/run_20261005_145619/glm_4bit_260864_1234_tensorfold_serial_4/result.jsone6a90599b29828a72275a773a68036ff1d70bb4b512ee393f3b09fda0c284151glm53_tensorfold065_bench/results/run_20261005_145619/glm_4bit_260864_1234_tensorfold_serial_6/result.json0bfda7c33b4c684ed69a3575690309f1b2b6d664769a067b6f2fd7be61f2bb40glm53_tensorfold065_bench/results/run_20261005_145619/glm_4bit_32768_1234_tensorfold_mtp_3/acceleration-comparison.json87ca05d7d3cd00341ebede309030d357faad3d672071aad0cf4fa36bd6f24d29glm53_tensorfold065_bench/results/run_20261005_145619/glm_4bit_32768_1234_tensorfold_mtp_3/result.jsonf92fabdb19a8067c2d68f711cd3aacbb81fd641fef6dbe29b03d438e88d65f1cglm53_tensorfold065_bench/results/run_20261005_145619/glm_4bit_32768_1234_tensorfold_serial_2/result.jsonffcc48f132cd40c0967cae14a6769f8ff8672adcae6ed4d6a846bd5e2126a758glm53_tensorfold065_bench/results/run_20261005_145619/glm_oq4_2048_1234_tensorfold_serial_8/result.json0fcbaeb05cb0de551c6c7a2ec8f6af9621e85df12c980f9605d68454ecace5e8glm53_tensorfold065_bench/results/run_20261005_145619/glm_oq4_2048_1234_tensorfold_serial_8/startup-failure-diagnosis.json7f8529fbda7d5ba24f616d089610c8c9a2e4b91995e616e6819b1e87fda5ff67glm53_tensorfold065_bench/results/run_20261005_200547/glm_oq4_2048_1234_tensorfold_mtp_1/result.jsonebc61ac1157bed146ecf2703bb92c512fe07c799904ff39fa7e04916394a4d78glm53_tensorfold065_bench/results/run_20261005_200547/glm_oq4_2048_1234_tensorfold_mtp_1/setup-stop-decision.json3c4fd790c1461c7d2fabf0b60a97e16d9160e0b1f9e9a60abfa4eb66e359e83cglm53_tensorfold065_bench/results/run_20261005_200547/glm_oq4_2048_1234_tensorfold_serial_0/result.jsoneaedf72b11f0eb2f80237df8b8e6361629f48fee478da5ce25eec11494d63f70glm53_tensorfold065_bench/results/run_20261005_213646/glm_oq4_2048_1234_tensorfold_mtp_1/acceleration-comparison.json8bf6186c36476d922bd2c683af3f15e26345a8b5ab5abf0b3bb9bb68825ca295glm53_tensorfold065_bench/results/run_20261005_213646/glm_oq4_2048_1234_tensorfold_mtp_1/result.jsonfdef58756be683a237c60f2016380c0a8b1affef1b750357b3b80357f4ce0343glm53_tensorfold065_bench/results/run_20261005_213646/glm_oq4_2048_1234_tensorfold_serial_0/result.jsond0b41716038f71a70c68cee1472d7e55f2e177a3943ff2a38750c3d52b74ec23glm53_tensorfold065_bench/results/run_20261005_213646/glm_oq4_2048_1234_tensorfold_serial_0/reference-comparison.json78d223bd69cf12b77bfb4e21876938ee9ffed67f63372f2b193b35d66a402e9eglm53_tensorfold065_bench/results/run_20261005_213646/glm_oq4_260864_1234_tensorfold_mtp_5/acceleration-unavailable.json0a4a2dd32f55a8e1640923ebb756fd00d38b29e13ad9adafe12a08b6ec1bb69cglm53_tensorfold065_bench/results/run_20261005_213646/glm_oq4_260864_1234_tensorfold_mtp_5/result.json9dc3a666ca25c0b0cb7233f01a4cc0d2974eb0946139f3e0f84e18ede5bc03f1glm53_tensorfold065_bench/results/run_20261005_213646/glm_oq4_260864_1234_tensorfold_serial_4/result.json1d5c00ec405f19e962121ba489dd11fa7004a2158fa02e835e5ee28c55747087glm53_tensorfold065_bench/results/run_20261005_213646/glm_oq4_260864_1234_tensorfold_serial_4/load-abort-observation.json1c1447c85d9696720e8c7a8f49dcb9b22483cf3a2b65317f1fc5db96b62e90a5glm53_tensorfold065_bench/results/run_20261005_213646/glm_oq4_260864_1234_tensorfold_serial_6/result.json070c75f4cc42b841db13becfe85d4ceb3ce7e38eebac5c1b8d55460ab59a1662glm53_tensorfold065_bench/results/run_20261005_213646/glm_oq4_260864_1234_tensorfold_serial_6/startup-failure-diagnosis.json1b715adc92319cff4b295bc6560a5a5ac1da5ae5c6374d121e221ea61555df2aglm53_tensorfold065_bench/results/run_20261005_213646/glm_oq4_32768_1234_tensorfold_mtp_3/acceleration-comparison.json83599797cde3ba35faf2cb9c14da56c620c43379a7c90c54ae9a4cdeacd54f4bglm53_tensorfold065_bench/results/run_20261005_213646/glm_oq4_32768_1234_tensorfold_mtp_3/result.json6fd2b02cd94519a7e1bd92b808491019a0d4ccd0d32bc3878acae7f70a0b3c87glm53_tensorfold065_bench/results/run_20261005_213646/glm_oq4_32768_1234_tensorfold_serial_2/result.jsonb45a42c8c77edc37c20d1c3ef004030bd9ac86e43917c1d972ee17221b0c8908glm53_tensorfold065_bench/results/run_20261005_230806/glm_oq4_260864_1234_tensorfold_serial_0/result.json6bafca6b7a0f8f2e35fd7a8dd5e61616460b7dd6a8d9c9649324334d135a7978glm53_tensorfold065_bench/results/run_20261005_230806/glm_oq4_260864_1234_tensorfold_serial_0/startup-failure-diagnosis.jsond23b1fbc10d75a29bbff4df17bb4fda09698540d926a5f17cc080919cabf48c6glm53_tensorfold065_bench/results/run_20261005_232901/glm_oq2_2048_1234_tensorfold_serial_0/result.json38b361be6cdb127fe0e84e187c35f934359f8259d292d6c6e56494d207dc680bglm53_tensorfold065_bench/results/run_20261005_232901/glm_oq2_2048_1234_tensorfold_serial_0/startup-failure-diagnosis.jsonf335b6b4e7697ed7a64ce249cf08d406e47c46160a085b04a6ed7c6cb9a35878glm53_tensorfold065_bench/results/run_20261005_234048/glm_oq4_2048_1234_tensorfold_serial_0/result.json16c7fa07a96add957a2c34bd1a1cd68b4425deecc1f13f0019de3fb3f4833dd1glm53_tensorfold065_bench/results/run_20261005_234048/glm_oq4_2048_1234_tensorfold_serial_0/loader-variant.json5cf96b7670909e3288e5abc14a3bd4294bf1ccb073c55473a4d4870e0f1b335dglm53_tensorfold065_bench/results/run_20261005_234048/glm_oq4_2048_1234_tensorfold_serial_0/reference-comparison.json5e10a57d789a1b0fee1ff45c5e78820c7c82fa2c71a160ca8f9f9910b3bc22cdglm53_tensorfold065_bench/results/run_20261005_234048/glm_oq4_260864_1234_tensorfold_serial_2/result.json4dec19a7227e4fc6989bd6ee9ca42a7814eab02bdae8a3d793c0baeaeedae156glm53_tensorfold065_bench/results/run_20261005_234048/glm_oq4_260864_1234_tensorfold_serial_2/loader-variant.json10a6ff27ef48a295912f6e25ed6df9effe8fafc2ef1402b484fab6c46a6fc430glm53_tensorfold065_bench/results/run_20261005_234048/glm_oq4_260864_1234_tensorfold_serial_2/interruption-diagnosis.json0460e40130de7d1efce221880718c4188fb9459862ad1051cd032b1851d291c2glm53_tensorfold065_bench/results/run_20261005_234048/glm_oq4_32768_1234_tensorfold_serial_1/result.jsona57f01469d2de18c639604fd7584e0b001d005c11a6d4d80cccc1eae4ebb93a4glm53_tensorfold065_bench/results/run_20261005_234048/glm_oq4_32768_1234_tensorfold_serial_1/loader-variant.json192c15d63369ecc898e1db8a0540e10fdc101a395443284440aceeb9b117bb76glm53_tensorfold065_bench/results/run_20261005_234048/glm_oq4_32768_1234_tensorfold_serial_1/reference-comparison.jsonca8d15986ccaf5c8c11e58e69094a6ce87d4dc11937c2aceb865e6ca02b9a1cbglm53_tensorfold065_bench/results/run_20261006_025508/glm_oq2_2048_1234_tensorfold_mtp_3/acceleration-comparison.json642dc5abb2db4c8284f610ff95e51ccf7e9e97f59d5fd613376e9cbb7d41241cglm53_tensorfold065_bench/results/run_20261006_025508/glm_oq2_2048_1234_tensorfold_mtp_3/result.jsonc3f79854cb666aa0915f4a13548faf8b2e21bd2d70bbbe058575eb4a763908f2glm53_tensorfold065_bench/results/run_20261006_025508/glm_oq2_2048_1234_tensorfold_mtp_3/loader-variant.json52ff813a33883ae59d2a2e0a3a8cb5e58ed171260167a6e560d3a0aa070418a9glm53_tensorfold065_bench/results/run_20261006_025508/glm_oq2_2048_1234_tensorfold_serial_2/result.json041ba974a28e8a4e79ec831ab68c144f841b2ba42053573ea8c9cd1f6777516cglm53_tensorfold065_bench/results/run_20261006_025508/glm_oq2_2048_1234_tensorfold_serial_2/loader-variant.jsona3ace8d81245832da30e93db290a078d1a2fecee311cad4acb1b82e27a5a2fd6glm53_tensorfold065_bench/results/run_20261006_025508/glm_oq2_260864_1234_tensorfold_mtp_7/result.jsonfb9845a13ba5860daeb63b2696a3ff0d19de479d6395a8d9aecdb7941265cbc1glm53_tensorfold065_bench/results/run_20261006_025508/glm_oq2_260864_1234_tensorfold_mtp_7/loader-variant.json4813ab8546633bf51af943980c8340e4be7182f11662c3bb503b4717b3b64d8aglm53_tensorfold065_bench/results/run_20261006_025508/glm_oq2_260864_1234_tensorfold_mtp_7/load-abort-observation.jsone2eb925b6f45af5b4c5e668fe31f3e6e94b8bebce572a5b990ec4022d9feb4c1glm53_tensorfold065_bench/results/run_20261006_025508/glm_oq2_260864_1234_tensorfold_serial_6/result.json78b17676ec82fb636c1f0e3d1c367667f19b37f2400318a9a4e823cb3c67550dglm53_tensorfold065_bench/results/run_20261006_025508/glm_oq2_260864_1234_tensorfold_serial_6/loader-variant.jsone8cf8ef91dda2a2b7c1b8a72e8323a4ab9e9512335b3bd8f2b455c4c3d3f13a1glm53_tensorfold065_bench/results/run_20261006_025508/glm_oq2_260864_1234_tensorfold_serial_6/load-abort-observation.json823a980cd3a944da5d74b176e7b1c248d4e1b46f2958c26929f5558ba70fd040glm53_tensorfold065_bench/results/run_20261006_025508/glm_oq2_32768_1234_tensorfold_mtp_5/acceleration-comparison.json5de81ac69ae550434f28adc9a8984a7289154c2b563a64cafe0c5517d734ddf5glm53_tensorfold065_bench/results/run_20261006_025508/glm_oq2_32768_1234_tensorfold_mtp_5/result.jsonf6a8475d2c7b06d596751f5411759a60a548acef2b3eef16d9960192ce801b58glm53_tensorfold065_bench/results/run_20261006_025508/glm_oq2_32768_1234_tensorfold_mtp_5/loader-variant.json98e32afe4df4789b085caedadb8d34b5e97bc09a780957576d1bd1ca3a8646c8glm53_tensorfold065_bench/results/run_20261006_025508/glm_oq2_32768_1234_tensorfold_serial_4/result.json3728a0f231bee5c0a010361149d7769744a9f6aed3d9ed256b5f5215be91b18cglm53_tensorfold065_bench/results/run_20261006_025508/glm_oq2_32768_1234_tensorfold_serial_4/loader-variant.json1fcd4c20fa8ed306e8b4069a09567586a509c4eb0084d8308028b552bfeecd31glm53_tensorfold065_bench/results/run_20261006_025508/glm_oq4_260864_1234_tensorfold_mtp_1/result.jsone6f6d820ca3d95b17dd7e8adf905e07cc1f86ff4876c67d5d92601d99e3916dcglm53_tensorfold065_bench/results/run_20261006_025508/glm_oq4_260864_1234_tensorfold_mtp_1/loader-variant.json773ccfbfed6bbd6d2b494d7cdbeac274968fdb0a6593e08aaf98128fec3d3975glm53_tensorfold065_bench/results/run_20261006_025508/glm_oq4_260864_1234_tensorfold_mtp_1/load-abort-observation.jsonedbbe17e094e0620fc451215ec793a0624919d38fe9273b9207b1c6b118e084fglm53_tensorfold065_bench/results/run_20261006_025508/glm_oq4_260864_1234_tensorfold_serial_0/result.json6a6ebd5daffc80c0a130ec6b60ceb11eef58afe1a2679becef37c6f756fc151aglm53_tensorfold065_bench/results/run_20261006_025508/glm_oq4_260864_1234_tensorfold_serial_0/loader-variant.jsonf4b5b83df472d02f7fe8daf7c17250cc5abd6432220acc36ec1587497d7cdcd0glm53_tensorfold065_bench/results/run_20261006_025508/glm_oq4_260864_1234_tensorfold_serial_0/load-abort-observation.json120cffe764e177899cd2d5828ff17fe87bef7d34be8e00638606a7edc31eca78glm53_tensorfold065_bench/results/run_20261006_063141/glm_oq4_260864_1234_tensorfold_serial_0/result.json9ebf08ccf803fc3c8902d697f12781827a1c4423dc809f325783d99beee26e26glm53_tensorfold065_bench/results/run_20261006_063141/glm_oq4_260864_1234_tensorfold_serial_0/startup-failure-diagnosis.jsonf4e3dbcde56bd6d4e9a7ac5e7515fdf4266f84d76b526146e0509c1037f02496glm53_tensorfold065_bench/results/run_20261006_073714/glm_oq4_260864_1234_tensorfold_mtp_0/result.jsona40e84680716cdb14ea43f5f8f173fffef96dec5bc6364e57e9406dacc82e4bbglm53_tensorfold065_bench/results/run_20261006_073714/glm_oq4_260864_1234_tensorfold_mtp_0/loader-variant.json97824160510ac4c412af23b3fb427a87debb2a8573b28f822953bd241b9b04dbglm53_tensorfold065_bench/results/run_20261006_073714/glm_oq4_260864_1234_tensorfold_mtp_0/background-intervention.json654a692ef6c48013efe24b0c5321398f304aaf872c7362dc2cb313b2ee9a1a83glm53_tensorfold065_bench/results/run_20261006_073714/glm_oq4_260864_1234_tensorfold_mtp_0/load-abort-observation.json05333f1d34152a9bba6285cfcf0cb41e6dd70bcaed1793856b27e9cdfcacc3a4glm53_bench/summary.jsone6a048eb289df371880c68602fd228689a220436337e02eef88234e6764e1354flashnext_bench/results/run_20260930_115151/summary.json65c4eb45ed6950e9d19378c84cd7a4990b3f4d7c4441390ef3652cd293f24fc7tensorfold_bench/results/run_20260930_000006/summary.json27852559b94ddc0a2bbdfd63dd225eea11dac68e1f51d51f6bfbab5586bf5343tensorfold_bench/results/run_20260930_000800/summary.jsone5ee62121bd02c0f51ec5fa5cdb30fa2e3dc66e656212045289cd67ed60c0365tensorfold_bench/results/run_20260930_005309/summary.json2d8835efce5046f8644a75ea10999583b284e816f5c215dbf334079e1538ca34e9_bench/results/run_20260929_163156/summary.json55f5fc2dee4cdcbeda111c4e3740b3cca404485c3735ede346be84c65cdbb1b8qwen38_27b_bench/summary.jsond81fd44bf79dfdf169dbad3eca56a5d5cd5a0ce76de5b454e4fe8994c8c86791qwen38_27b_bench/results/run_20261001_173331/summary.jsonef3639e05b0989aab98a307a745ccf556568ef42d04de972b3cbb6c2ff4ef29eqwen38_27b_bench/results/run_20261001_180533/summary.json28beed756cb21f8a184f94d58a1ba02e09b867579f0153d278fe8cebaa8fb581qwen38_27b_bench/results/run_20261001_182755/summary.json4412f43bdfa53ffd7397f784ae4db46329072588b20f96cddc7d43eba06c9f2bqwen38_27b_bench/results/run_20261001_184030/summary.jsonca7cb69a7cc5b2e6e52dbef5234a191c6769f0423822309ff686795265db00famlxfast_bench/results/c32k_fans/summary.json9d5074cc540e274e4f4620699f2af4770f9badb2fba3bbd7a58dcd4af86649bdqwen38_variants_bench/manifest.jsondbcd2dba86d7c8cbd8589d831ec7ceede3ffaa1323d4c6372cdd6cbed22ee613eight_models_bench/manifest.jsone968e3ec418c7fdb5739a12a692bb8f2b3eab55445a0ba0839be9984a2adea83glm53_tensorfold065_bench/manifest.json2ca5581a2cd6ca601882955ddf5e68cb972e5682813f624f0b6c56582b9c92eaqwen38_variants_bench/artifacts/tf_flash.json5ecd4c19dfb749da2a6aafe3f38996b247cdc67ce1a6655f2e0bd667e5e2c1b4glm53_tensorfold065_bench/weight-formats.json1c5c0d615a4b5bf913596c494a9965f500ecd6b27492dab0836350a5646652f3docs/28092026_mlxfast_32k_benchmarks.md7204cab54712125b677ae8b5bcd1ea3b07ce315d5308fce2c833296d76195d99docs/29092026_macmon_temperature_fix.mdd565919a794409c24081c339b9d8ce5958ec02777407a211e702ff33b1538419e9_bench/results/run_20260929_163156/REPORT.md02a0122e2d9244f9b1a72b0be84fb195249da98d4a49ccec4a42a1ad1c38ccf0docs/20260929_tensorfold_nemotron_256k.mdcf69c54621becb9159c340bc4d9a4f510eb3d00113df90e1bf0da7fd3fd90fd1docs/20260930_tensorfold_flashnext_256k.md7ea752afd762f8c3dc59d9c74b669a1352908c3cad7270ef977c37bc0fe3860ddocs/20260930_glm53_flash_variants.md021c5d91a83b16336459b8ba63363bb531424978c2b2de8508c480d9d068a88adocs/01102026_qwen38_27b_mlx_benchmark.md0d6a504c41d62d067c18c7697e53cb37bb1b5691d5c938c2822f2d14aee0843bdocs/02102026_eight_models_256k_benchmarks.md4ef880abc60d77f1e73f52f9a19e06c07bf61e3273ad281cd2c831d89c10ee48docs/04102026_qwen38_variants_256k.mddee30bdd4fedce293a914939e1372197f3f63421585115d000ac1375e798553bdocs/02102026_256k_100tps_candidates.md9be02253d1bf228e1a20d39b0a7bf003af9dd8a38d61e48b3ff95b24c29fdb7ceight_models_bench/mimo/INVESTIGATION.md461a66d9fb0688ef7726538da380d33939027da67976d2f5ee4351da5fea5308qwen38_variants_bench/METHOD.md0e016d5aeebdffbfe7324d4ef6b45092a3d456d3a724af121789f974b4569211docs/05102026_glm53_tensorfold065.md3055bbb956eda9d8e7c6b6619e21b48cd02e3de6379ff19423588aa88eb0da8bglm53_tensorfold065_bench/README.md08302ed80f9153548b30361f66efe993007e0688179d876e5191e482c09dfc45glm53_tensorfold065_bench/tensorfold-source.jsond281e3547ce9e82703aa542a23544593d1bf65d81d475b8dea096a383f938965glm53_tensorfold065_bench/protocol-comparison.jsond8608f11dfe98bff18c6b4ed9dd1b33e78cbb584d52341c760559624fd6dcdf2glm53_tensorfold065_bench/direct-load-plan.json8b557f20aabb4eb55809760cdc19b6bcd51fbbf6f5a31b39b0c80e5d9d09076cglm53_tensorfold065_bench/direct-load-decision.json3c4fd790c1461c7d2fabf0b60a97e16d9160e0b1f9e9a60abfa4eb66e359e83cglm53_tensorfold065_bench/eager-load-plan.json88b209891a569e2702e15925e013817af8147240a2562fba3102d8fc157d7939glm53_tensorfold065_bench/eager-load-decision.json7144b10a001c8fec722b3b5b8f17d3b913da8d93747d9c22b2540c68350dd09aglm53_tensorfold065_bench/eager-loader-tests.json6d7d6bfb07564816995e7845e66ea0587322e8f09139b1a78a75e9f7bf3d7e5dglm53_tensorfold065_bench/eager_weights.py5bcb0ec46a185d500aa65635dc034882059d37164b2b858b135c4f8e4e7186d6glm53_tensorfold065_bench/loader-investigation/hypothesis.json0dc9b400f687cde35e7dcce3aac021250901ac4e858f604b112a5039c366683eglm53_tensorfold065_bench/loader-investigation/sources.json5275649843f025f166cadd4641cf43b2cf32f08fb44a51295fb3bef3fd76ee9cqwen38_variants_bench/tensorfold-source.jsond281e3547ce9e82703aa542a23544593d1bf65d81d475b8dea096a383f938965qwen38_variants_bench/tensorfold-integrity.jsone48e2cb7bd40fba9769057d8e693824ff652f0cf696b7b28e000aa02b2971465glm53_tensorfold065_bench/runtime-integrity-start.jsona67279ad02187e23e1b229d4296a094f8ea07ef077945f21c9e69e24a1569f91qwen38_variants_bench/runtime-integrity.json0b1e29d638f863686c6323a9c640341d03101ae4cabab747f98697dcccd74ca6tensorfold_bench/requirements.lock.txt60edae2c2d4c84b38508489563febbee318755373f89a0408c739d1473d93ec6flashnext_bench/requirements.lock.txt60edae2c2d4c84b38508489563febbee318755373f89a0408c739d1473d93ec6glm53_bench/runtime-provenance.jsoneddd34b198b4b2a13333314396d02f1f2a1dd5fa902ebabc2c97181ee43f50cfglm53_bench/runtime.patch13667562e648fae56db51a20b2633a7653cb5655bdc9709ce84c65a3079d3d66eight_models_bench/runtime-integrity.json23126377d8ab7cbe594c72792728ca104a17d9c936d6d0e93c40375f7f80a0fdeight_models_bench/worker.py90a1e215107bf104c6bb6aaa2cb70e15476fdf2d2922fe03afb1423f82351041eight_models_bench/ling_adapter.py2cab71f8ad08c24865c518389db9e395f35d41f83971737d4dad5ff6f94a86d6eight_models_bench/ling/ADAPTER.md2b13edfcee06367ae3e902c03d5441eb2607738e5dc3ed0f75e4968e158c2d79eight_models_bench/accel_engines.py97f0feece64535d1dc8e43a836523241b8d078d939810ace098e94401a4d584feight_models_bench/mtplx-runtime-integrity.json5fbf3f8c0d850180e3c7fe52c00effa78b98ffc244962779890931fef12acd17qwen38_27b_bench/runtime-version.jsonda9b37189d08723c94d93841773f80d55ef31c5c49c2b2b60c10fdbc2df2dff4qwen38_27b_bench/runtime-verification.json1d79f3652243ba0786a58e7d94700ceab46dcac5c15f07102b3329c4fa2df502e9_bench/results/run_20260929_163156/environment.txt5bc83b7a204780134fe66edd39d000a3cd4ba4e2627f75eb5c6c6f8d456ceb76tools/engine-e9/Package.swiftc4f31f12999f2a1243be6d00e393ddcfff7391961a4cdd0cdf091789fec8c7d2mlxfast_bench/build_trees.shb68d8ad11c7622d95bbba65597684bbda1f3dbdd282366a329a9ade2fb64f987docs/28092026_mlxfast_256k_plan.md630ba9431abda61e2a45ec5ca2c8ec25e06995f40088b1ba5cad9c95843a0d9dmlxfast_bench/results/c32k_fans/ctl_serial_1.json130c8a4818ca979a6724bb30eca2ef904f1387ccbcdb53ee42b93bd9b1e15fddmlxfast_bench/results/c32k_fans/winglock_serial.json0039e94e9a041f5987f699631a4ecb468e65636d426bc183dbcb0594a1b19538eight_models_bench/results/run_20261002_153149/ling124_2048_1234_mlx-lm_serial_0/ling-adapter.json8611d57154fa96a6373d5ce5b43a9a9340f4ade3eaaa5e1ff9d898d0b375fc95eight_models_bench/results/run_20261002_153149/ling124_260864_1234_mlx-lm_serial_2/ling-adapter.json8611d57154fa96a6373d5ce5b43a9a9340f4ade3eaaa5e1ff9d898d0b375fc95eight_models_bench/results/run_20261002_153149/ling124_32768_1234_mlx-lm_serial_1/ling-adapter.json8611d57154fa96a6373d5ce5b43a9a9340f4ade3eaaa5e1ff9d898d0b375fc95eight_models_bench/results/run_20261002_173233/ling124_260864_1234_mlx-lm_serial_6/ling-adapter.json8611d57154fa96a6373d5ce5b43a9a9340f4ade3eaaa5e1ff9d898d0b375fc95mlxfast_bench/results/c32k_fans/ctl_dflash10.json4d57d35cc697bb7ce30cf77aff68a8095c4ef3082483b7091059ed7e46075dffmlxfast_bench/results/c32k_fans/winglock_dfsafe10.jsonc645da952fdde079a186054fb791e495a001a7bec766275c6c928b69df1ce449qwen38_variants_bench/results/run_20261004_225650/tf_flash_260864_1234_tensorfold_mtp_1/result.jsona0ce820af154ac25fd6f2e2f7a8c2f339c3c851834e3c61d9b662ae1062e6357
Related articles: the original speed and context target, MLX versus llama.cpp, and the earlier GPU-limit investigation. Runtime source: TensorFold and MTPLX.